At least 1 item(s) required
At least 1 item(s) required
When true, filler words like "hmm" and "ahh," interjections, and natural background sounds will be added to the conversation.
Controls the randomness of the speech output. Higher values produce more creative and varied delivery, while lower values make the output more predictable and focused. Default value: 1
README
Complete guide to using google/gemini-3-8-flash-tts
Gemini 3.8 Flash TTS API – Create Custom Voices with 30-Second Voice Cloning
Build with Google Gemini 3.8 Flash TTS on Kie AI. Create original voices from natural language, replicate voices from short audio samples, and generate high-fidelity, expressive speech across 130 languages.
Create and Replicate Voices with Gemini 3.8 Flash TTS API
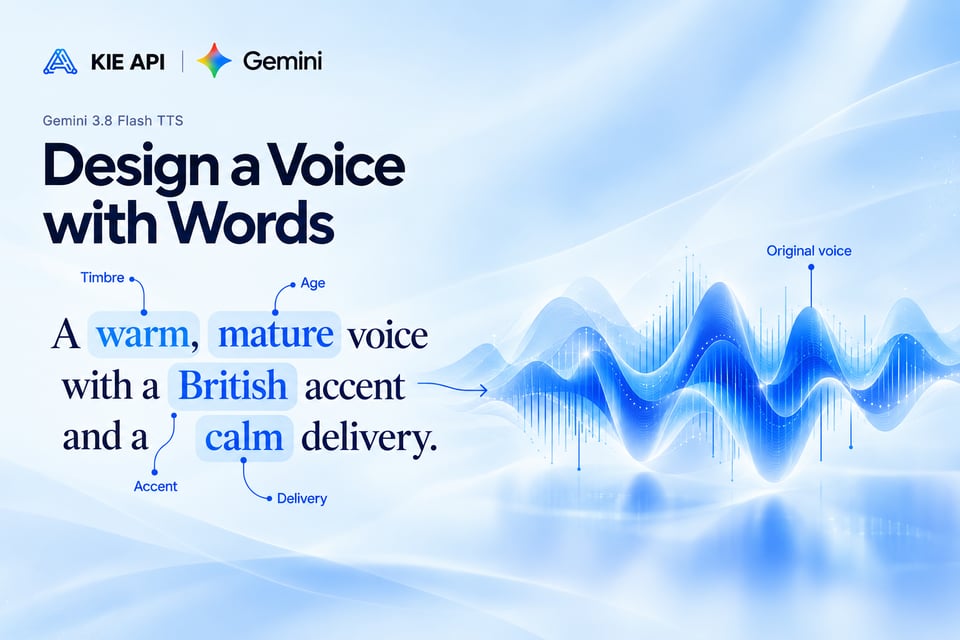
Design Original Voices from Natural Language
Use Gemini 3.8 Flash TTS on Kie AI to create original voices from simple text descriptions. Define the voice you need through characteristics such as age, timbre, accent, tone, and delivery style, then use it across your text-to-speech workflows through Kie AI.
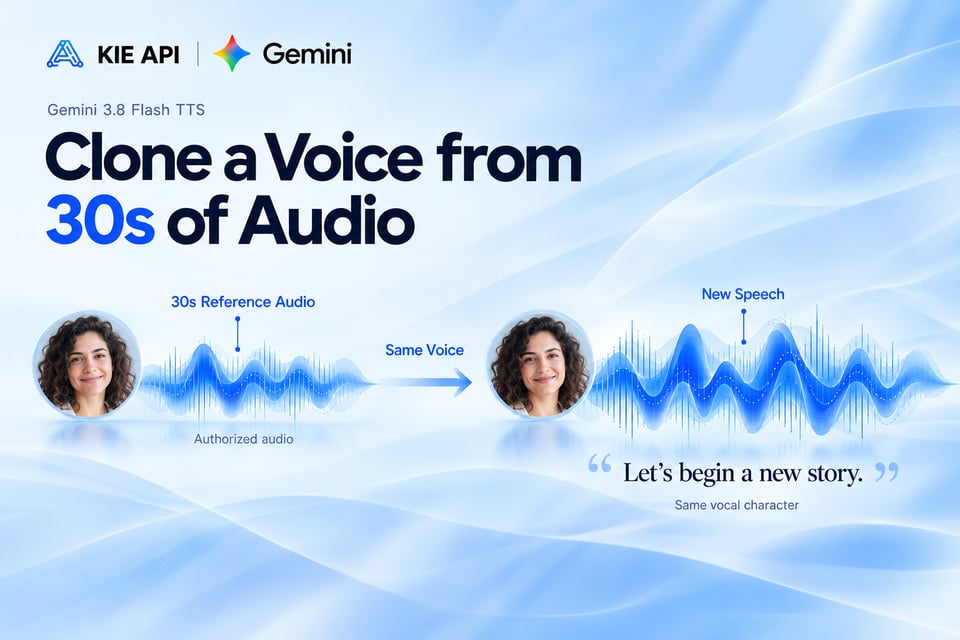
Replicate a Voice from Just 30 Seconds of Audio
With the Gemini 3.8 Flash TTS API on Kie AI, you can replicate a voice from approximately 30 seconds of authorized reference audio. Preserve the speaker’s recognizable vocal characteristics and generate new speech with the replicated voice for narration, characters, branded audio, and other applications.
Key Features of Gemini 3.8 Flash TTS API on Kie AI
Generate Studio-Grade Speech with Gemini 3.8 Flash TTS API
Create clear, natural, and expressive audio with the Gemini 3.8 Flash TTS API. The model delivers high acoustic fidelity, natural cadence, and detailed acting nuance while following your voice directions closely. Use the Gemini 3.8 text-to-speech API for professional narration, character dialogue, podcasts, audiobooks, and other applications where voice quality and expressive delivery matter.
Design Custom Voices with Google Gemini 3.8 Flash TTS
Go beyond fixed voice presets with advanced Voice Design. Google Gemini 3.8 Flash TTS API lets you create original voice personas by describing the role, accent, tone, and vocal characteristics you want in natural language. Build distinctive character voices, narrators, or brand voices that better match the identity and creative direction of your application.
Direct Expressive Voice Acting Line by Line
Control how each line sounds instead of using one fixed speaking style. The Gemini TTS API supports turn-level directions for tone, pace, emotion, and delivery, along with natural vocal events such as laughter, sighs, breaths, coughs, and short pauses. This precise control helps developers create more realistic storytelling, dialogue, character voices, and expressive audio experiences.
Keep Voices Consistent Across Long-Form Audio
Generate longer speech without losing the identity of your selected voice. Gemini 3.8 Flash TTS API maintains consistent timbre, volume, voice characteristics, and acoustic tone across extended dialogue and multi-minute narration with minimal voice drift. This long-form stability makes the model well suited to audiobooks, podcasts, educational narration, and other continuous audio experiences.
Create Natural Multi-Speaker Dialogue with Gemini TTS API
Turn scripts into expressive conversations while keeping speakers clear and distinct. With Gemini 3.8 Flash TTS, developers can assign different voices and delivery styles to individual speakers, maintain natural turn-taking, and add vocal reactions throughout a scene. Use the Gemini TTS API to power podcasts, interactive characters, dramatic dialogue, and conversational voice experiences.
Generate Speech Across 130 Languages and Regional Accents
Build multilingual voice experiences with support for 130 languages, automatic language detection, regional accents, and minority dialects. The Google Gemini 3.8 Flash TTS API also supports IPA pronunciation overrides for words that need precise pronunciation. This gives developers more control when creating localized narration, global content, character voices, and speech applications for different markets.
How to Use Gemini 3.8 Flash TTS API on Kie AI
Step 1: Try Gemini 3.8 Flash TTS Free in the Playground
Step 2: Customize Your Voice and Speech
Step 3: Get Your Kie AI API Key
Step 4: Integrate Gemini 3.8 Flash TTS API into Your App
Gemini 3.8 Flash TTS vs Gemini 3.8 Flash-Lite TTS
Gemini 3.8 Flash TTS is designed for applications where voice quality, expressive performance, and creative control matter most, while Gemini 3.8 Flash-Lite TTS focuses more on speed, throughput, and cost-efficient speech generation.
| Gemini 3.8 Flash TTS | Gemini 3.8 Flash-Lite TTS | |
|---|---|---|
| Primary Focus | Voice fidelity & creative control | Speed & cost efficiency |
| Supported Languages | 130 | 101 |
| Best For | Creative & professional audio | High-volume speech generation |
| Long-Form Narration | Supported | Supported |
| Voice Replication | Supported | Supported |
| Typical Workloads | Audiobooks, dialogue, characters | Voice agents, read-aloud, bulk audio |
What Can You Build with Gemini 3.8 Flash TTS API
Create AI Audiobooks with Gemini 3.8 Text-to-Speech API
Turn books, stories, and long scripts into expressive spoken audio with consistent voice quality. The Gemini 3.8 Flash TTS API maintains stable voice identity, natural pacing, and acting nuance across extended narration, making it well suited to AI audiobooks, serialized stories, educational audio, and other long-form text-to-speech applications.
Generate AI Podcasts and Multi-Speaker Audio
Build podcast-style conversations with distinct speakers, natural turn-taking, and individual delivery styles. Google Gemini 3.8 Flash TTS API can transform written scripts into engaging multi-speaker audio for AI podcasts, interviews, dialogue shows, and automated audio content without relying on one fixed narrator voice.
Build Character Voices for Games and Interactive Media
Create distinctive voices for game characters, virtual worlds, interactive stories, and entertainment apps. With custom Voice Design and expressive performance control, Gemini 3.8 Flash TTS lets developers define character personalities, accents, vocal styles, and emotional delivery to make digital characters feel more individual and engaging.
Power Expressive AI Voice Agents with Gemini TTS API
Give conversational AI more natural and responsive speech. The Gemini TTS API supports expressive delivery, conversational pacing, vocal reactions, and distinct voice identities for customer experiences, virtual assistants, interactive agents, and other voice-enabled SaaS products that need more than basic text-to-speech output.
Create Multilingual Dubbing and Localized Voice Content
Use the Gemini 3.8 Flash TTS API to generate localized speech across 130 supported languages, including regional accents and dialects. Developers can build multilingual dubbing, video localization, global learning content, and international media workflows while adapting pronunciation and vocal delivery for different audiences.
Design Brand Voices and Professional Audio Experiences
Create a recognizable voice identity for products, campaigns, apps, and digital experiences with Google Gemini 3.8 Flash TTS. Design a custom voice that matches your brand personality and reuse it across product narration, branded content, marketing audio, guided experiences, and other professional voice applications.
Why Choose Kie AI for Gemini 3.8 Flash TTS API
Access Gemini 3.8 Flash TTS and Flash-Lite TTS APIs on Kie AI
Use both Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS through Kie AI. Choose Flash TTS for high-fidelity, expressive voice generation or Flash-Lite TTS for high-volume, cost-efficient workloads—all within the same platform.
Try Gemini 3.8 Flash TTS Free Online
Test Gemini 3.8 Flash TTS free in the Kie AI playground before integrating the API. Enter your text, explore voice settings, and generate sample audio online to see how the model fits your application before moving into development.
Access Gemini TTS API and More AI Voice Models
Go beyond the Google Gemini 3.8 Flash TTS API and access other text-to-speech models through Kie AI. Developers can explore different TTS options for voice generation, narration, conversational AI, and other audio workflows without relying on a single model.
Get Affordable Gemini 3.8 Flash TTS API Pricing
Build AI voice features with affordable, usage-based access to the Gemini 3.8 Flash TTS API. Kie AI offers flexible pricing for developers and SaaS teams, making it easier to control text-to-speech costs as usage grows from testing to production.
Integrate and Manage Multiple TTS APIs in One Place
Connect the Gemini TTS API and other AI models through one developer-friendly platform. Kie AI simplifies API integration, usage management, and multi-model workflows, so you can spend less time managing separate providers and more time building your product.
Get Developer Support for Gemini 3.8 Text-to-Speech API
Get help throughout your Gemini 3.8 text-to-speech API workflow, from initial testing to production integration. Kie AI customer support can assist with API usage, integration questions, account issues, and other problems that may come up while building your application.