Automatically append previous messages to maintain multi-turn context. May increase token usage.
How can I help you today?
README
Complete guide to using deepseek-v4-1-flash
DeepSeek V4.1 Flash API for Multimodal Chat
DeepSeek designed V4.1 Flash for greater capability, faster inference and higher throughput: a 552B-parameter MoE model that uses just 8B active parameters for input and 16B for output, reads images and text natively and, per its model card, supports contexts of up to one million tokens. The October 17 update, DeepSeek V4.1 Flash 1017, keeps the same model name and request format. On Kie.ai, you call the DeepSeek 4.1 Flash API on the OpenAI Responses-compatible /openai/v1/responses endpoint.
New to DeepSeek-V4.1-Flash? Read what it is and how it compares →
DeepSeek V4.1 Flash API Parameters on Kie.ai
| Parameter | Value |
|---|---|
| Model | deepseek-v4-1-flash |
| Endpoint | POST /openai/v1/responses, compatible with the OpenAI Responses API |
| Context window | Up to 1M tokens (DeepSeek Hugging Face model card) |
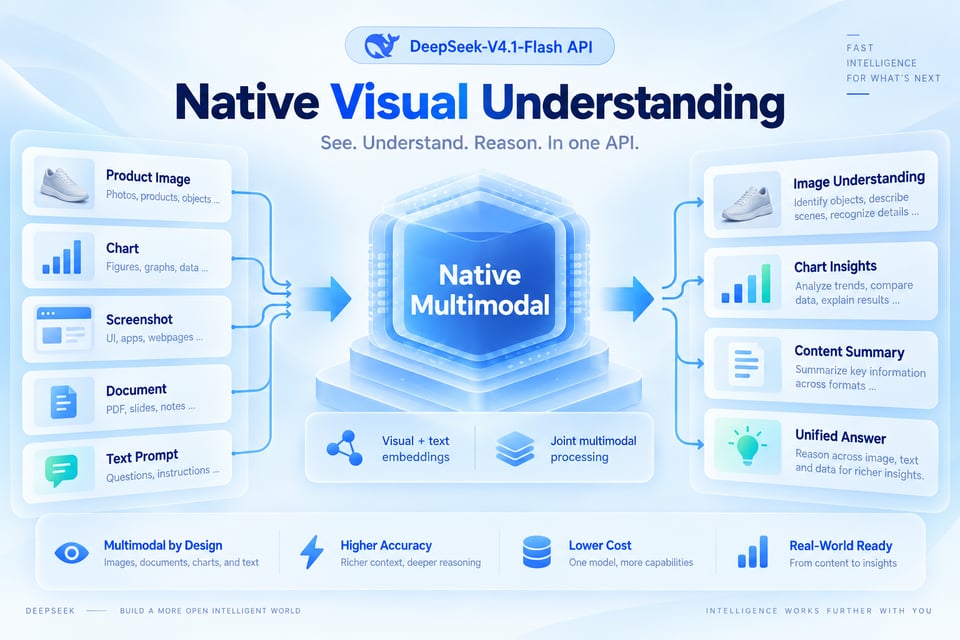
| Input types | Text and images (input_text and input_image parts in one message); output is text |
| Thinking | On by default; reasoning.effort accepts none, minimal, low, medium, high, xhigh and max (none turns thinking off) |
| Tools | Function tools only; tool_choice auto (default), required or one named function |
| Structured output | text.format json_object or json_schema |
| Streaming | stream true or false |
| Not supported | max_output_tokens, temperature and top_p have no effect on this model |
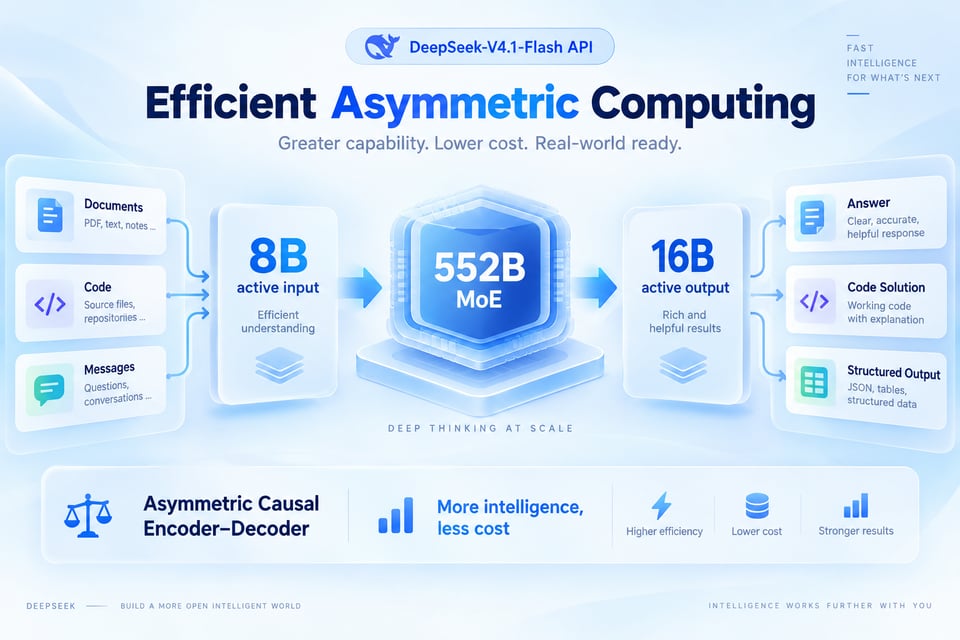
| Architecture | 552B-parameter MoE, Causal Encoder-Decoder, 8B active parameters for input and 16B for output (DeepSeek) |
Key Features of the DeepSeek V4.1 Flash API
Native Image Understanding
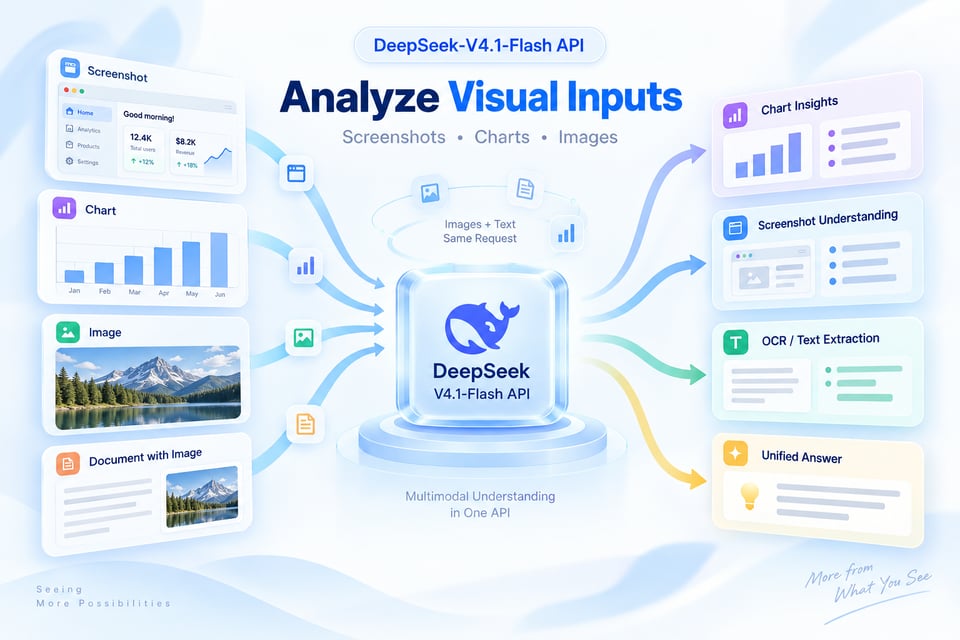
DeepSeek V4.1 Flash processes images and text natively. Mix input_image and input_text parts in one message; image_url takes a publicly reachable URL or a data:image base64 string. In our test on Kie.ai, it read the headline on a banner image exactly and named the glowing sun in the picture.
Efficient 552B MoE Architecture
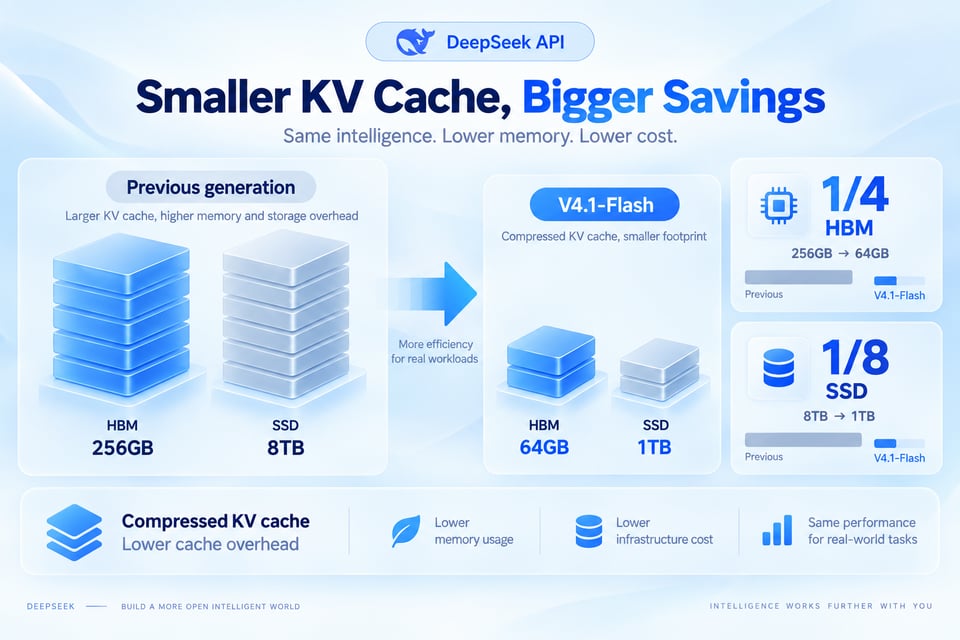
DeepSeek describes V4.1 Flash as the smallest model in its new architecture family: a 552B-parameter Mixture-of-Experts model on a Causal Encoder-Decoder architecture that uses just 8B active parameters for input and 16B for output. DeepSeek reports a KV cache that needs 1/4 the HBM and 1/8 the SSD storage of the previous generation.
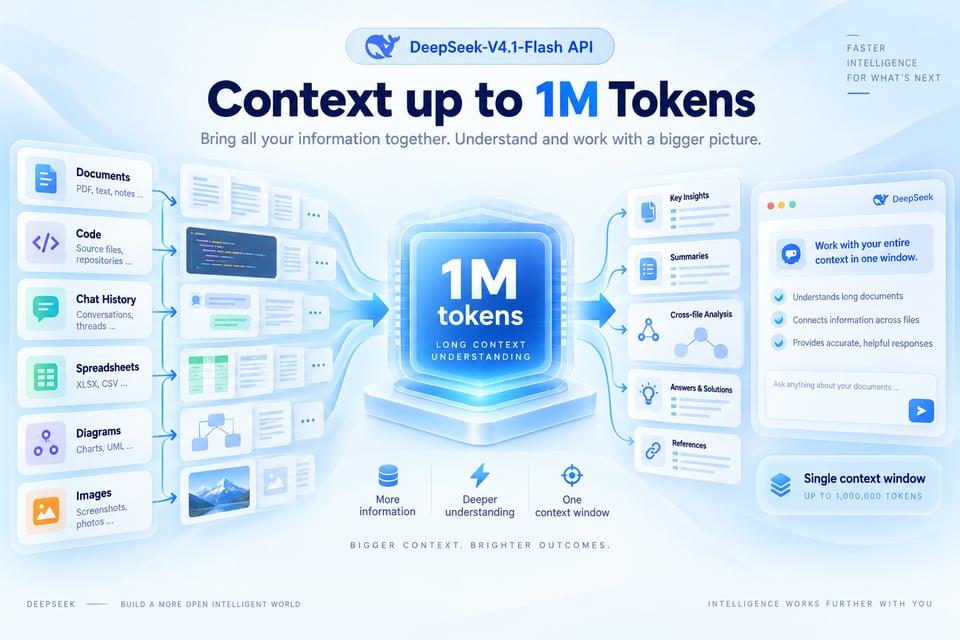
Up to 1M Tokens of Context
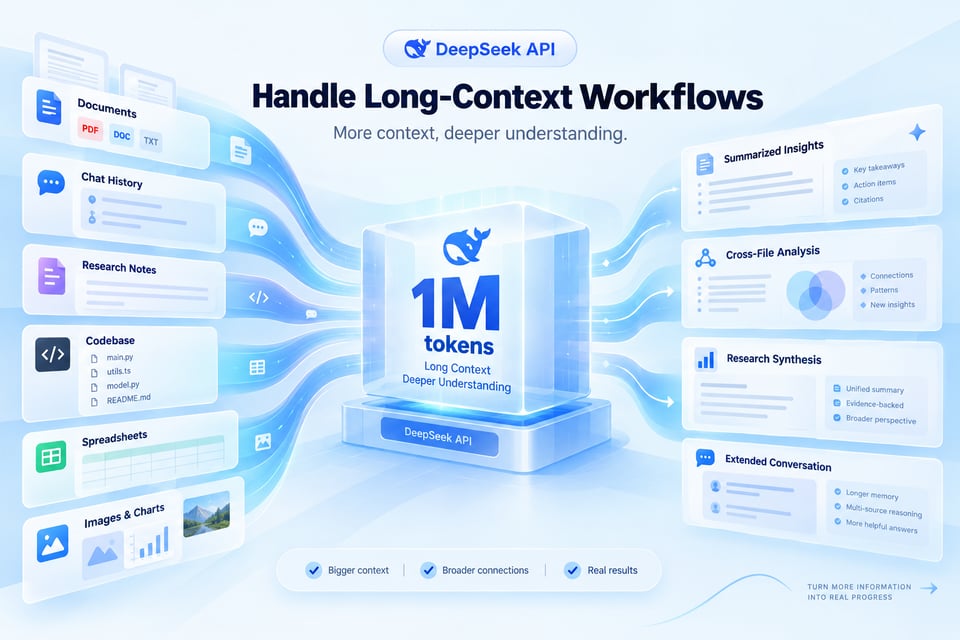
According to DeepSeek's model card, V4.1 Flash handles contexts of up to one million tokens, which leaves room for long documents and large codebases. The Kie.ai docs list no separate context limit for this model.
Thinking You Can Turn Up or Off
The model thinks by default. Set reasoning.effort to none to turn thinking off, minimal to keep it brief, or low, medium, high, xhigh or max for deeper reasoning.
Function Tools and JSON Output
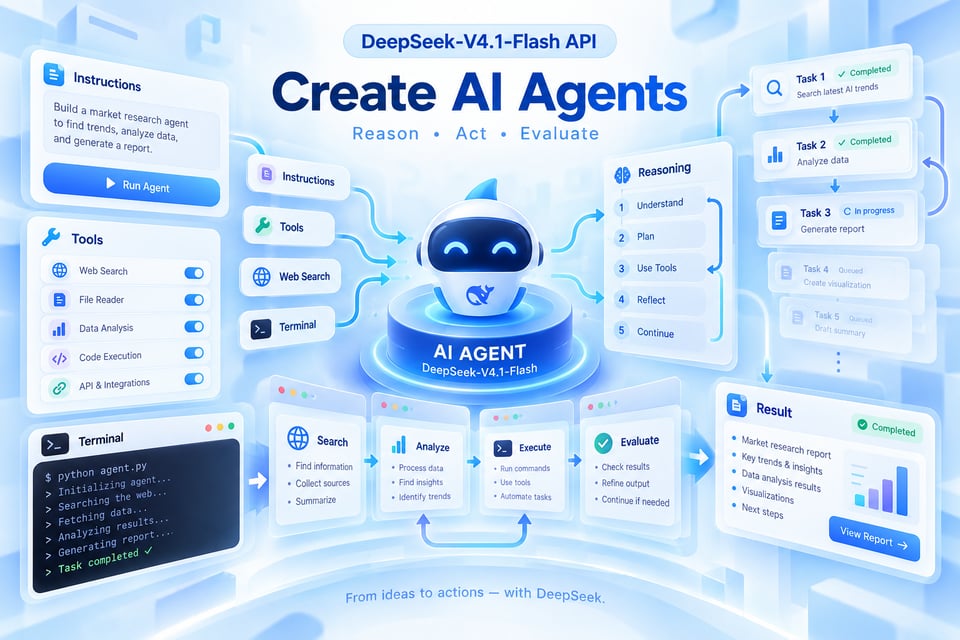
Declare function tools and let the model choose with tool_choice auto, require a call, or pin one named function; send results back as function_call_output paired by call_id. Set text.format to json_object or json_schema for output your code can parse.
The 1017 Update, Same Integration
DeepSeek V4.1 Flash 1017, released on October 17, 2026, brings what DeepSeek calls stronger benchmark performance, faster task completion and shorter outputs than the previous version. The model name, endpoint and request format are unchanged, so existing integrations keep working.
DeepSeek V4.1 Flash 1017 Benchmark Results vs the Previous Version
DeepSeek-reported results from its Hugging Face model card for the 1017 update. Terminal-Bench 4.0 ran with the Claude Code harness and DeepSWE v1.1 with the Mini-SWE-V2 harness.
| Benchmark | V4.1 Flash 1017 | Previous V4.1 Flash |
|---|---|---|
| HLE (without tools) | 42.6 | 36.8 |
| Terminal-Bench 4.0 | 42.3 | 31.2 |
| DeepSWE v1.1 | 77.0 | 74.2 |
| ProgramBench | 29.1 | 20.3 |
| NL2Repo-Bench | 68.2 | 65.4 |
| Apex Bench v1.1 | 72.1 | 64.6 |
| Chartography (with tools) | 83.0 | 78.9 |
| BabyVision (with tools) | 92.5 | 89.6 |
How to Use the DeepSeek V4.1 Flash API on Kie.ai
Step 1. Get Your API Key
Step 2. Send a Request
Step 3. Add Images, Tools and JSON Output
Why Use the DeepSeek V4.1 Flash API on Kie.ai
Same Key Across the Kie.ai Market
All models in the Kie.ai market use the same authentication method: an Authorization: Bearer YOUR_API_KEY header with the key from your Kie.ai API Key Management page.
Free Credits and One Balance
New Kie.ai users receive 80 free credits for testing. Your account has one credit balance that all generation services draw from, and you can check it with the Get Remaining Credits API.
Nothing to Host or Install
Kie.ai provides this model as an API with a playground; there is no app to download or install. There are no GPUs or model weights to manage.
What You Can Build with the DeepSeek V4.1 Flash API
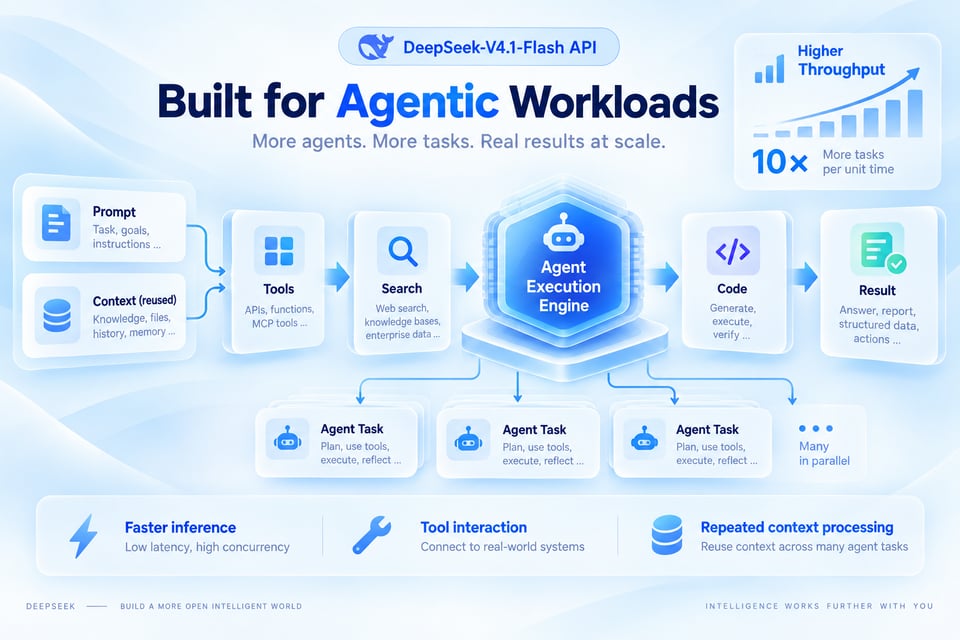
DeepSeek designed V4.1 Flash for faster inference and higher throughput. For a larger open-weight model with a 1-million-token context window on the same endpoint, see the Kimi K3.1 Pro API.
Chat and Q&A on Images
Answering questions about screenshots, charts, banners and photos alongside text in the same message.
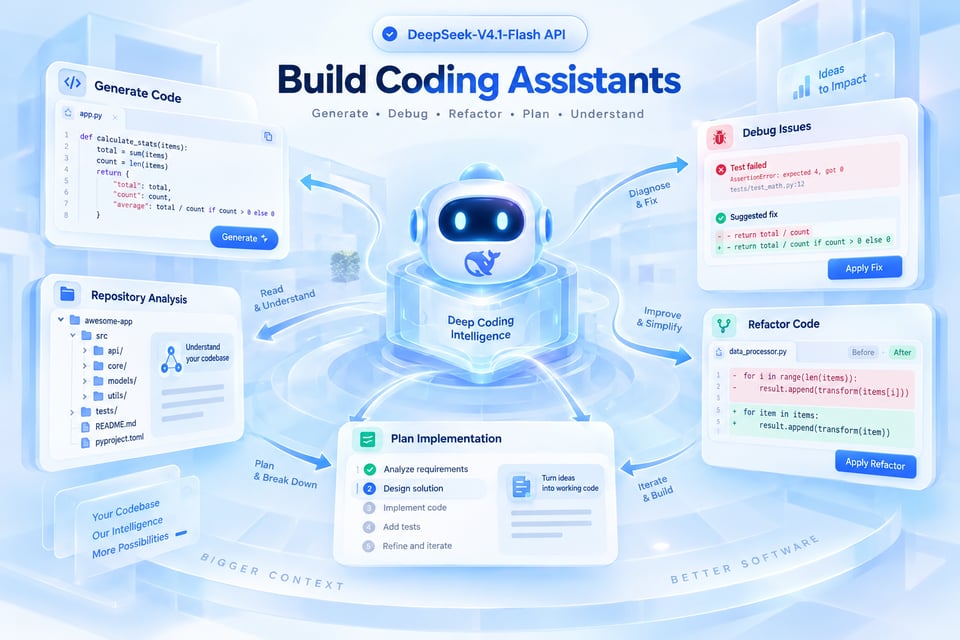
Long-Document and Codebase Questions
Working through long documents or large codebases in a single request; DeepSeek's model card lists contexts of up to one million tokens.
Structured Extraction
Pulling fields from text or images into JSON that follows your schema with text.format json_schema.
High-Volume Chat Features
Powering chat features where throughput matters, with thinking turned down or off for simple requests.