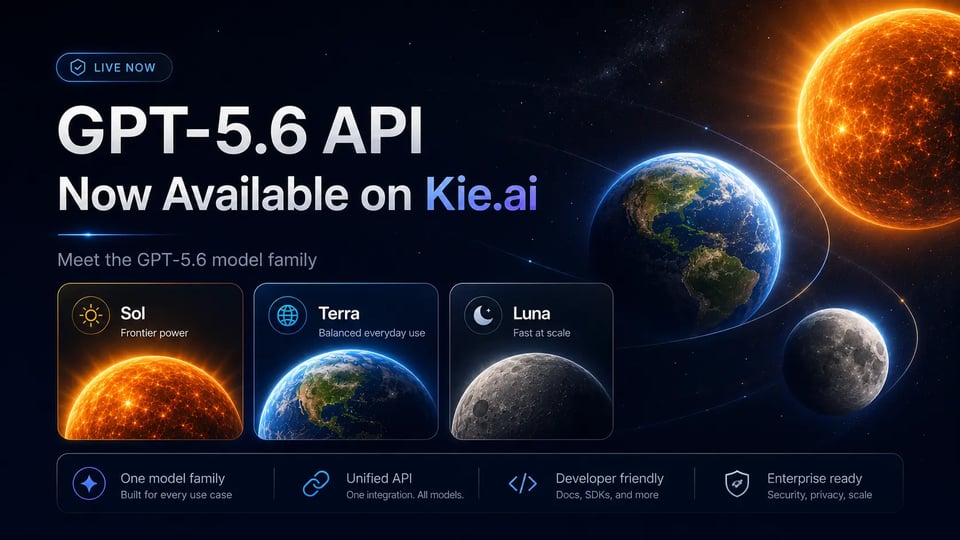
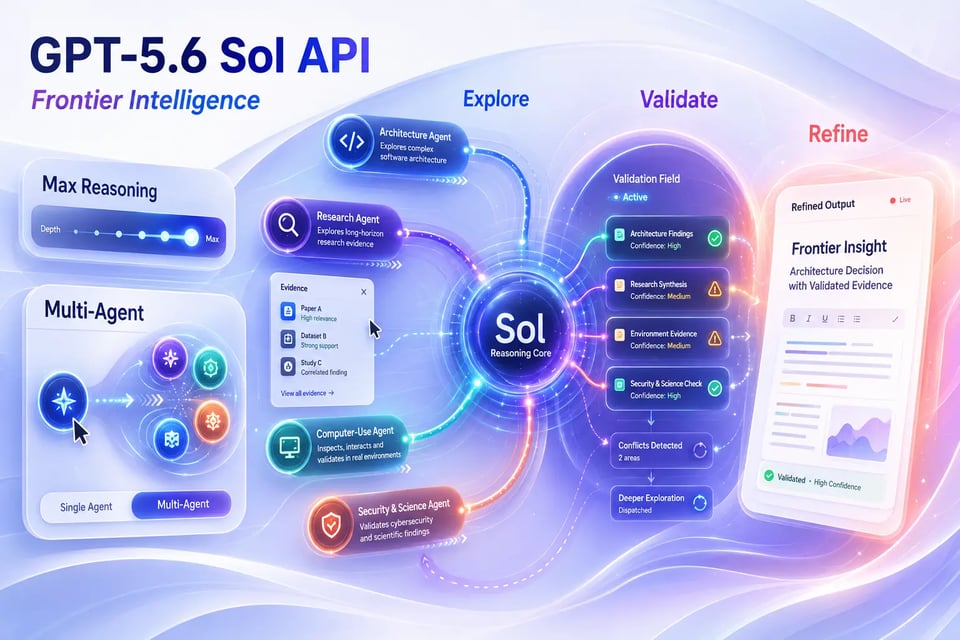
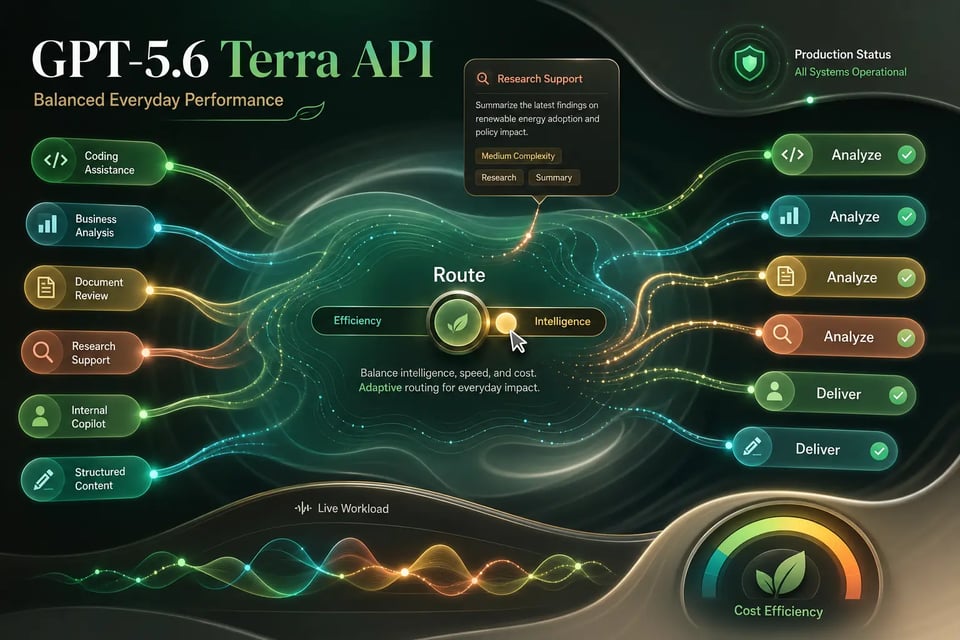
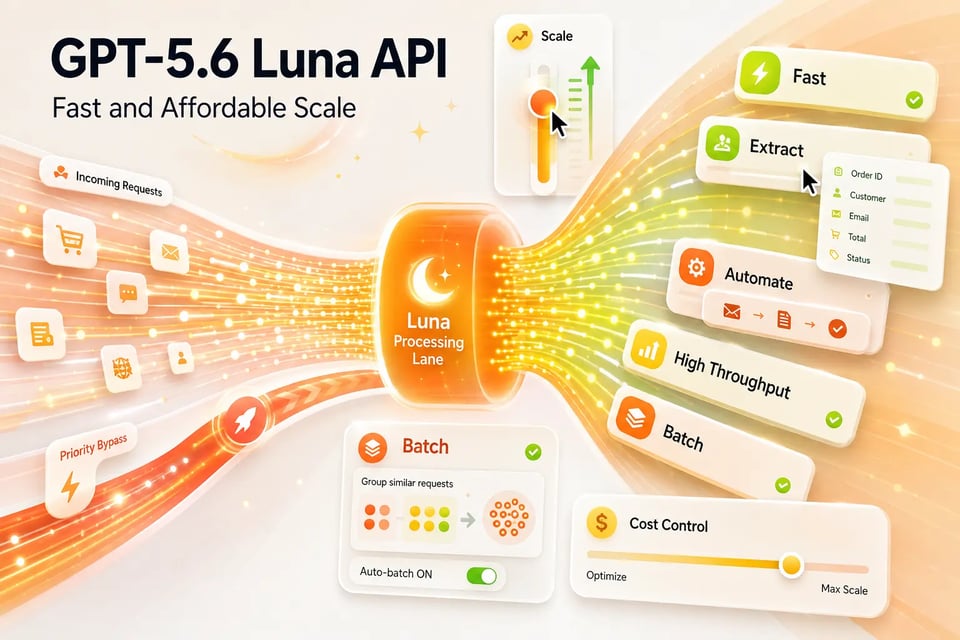
GPT-5.6 unites Sol, Terra, and Luna in a three-tier family built for frontier intelligence, efficient everyday work, and fast high-volume execution across technical and professional tasks.

Model Type:
Pricing: Input 280 credits / 1M tokens (≈ $1.40), Cached Input 28 credits / 1M tokens (≈ $0.14), Cache Writes 350 credits / 1M tokens (≈ $1.75), Output 1680 credits / 1M tokens (≈ $8.40). ~72% cheaper than official pricing. High-tier top-ups (+10% bonus) bring effective pricing down to ~90% of the above.

Automatically append previous messages to maintain multi-turn context. May increase token usage.

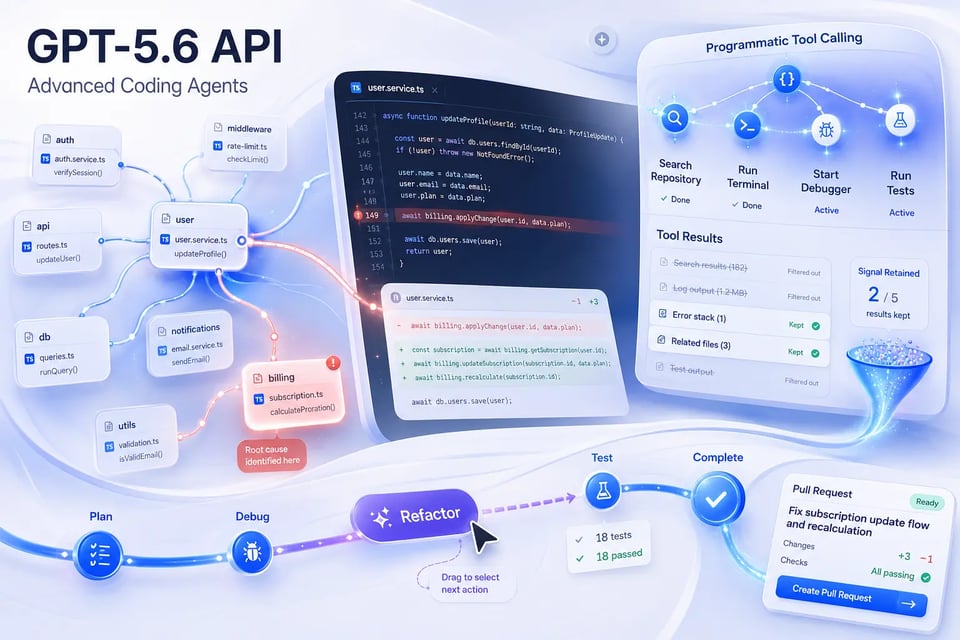
Function calling
Web Access
Reasoning effort
Stream Response

How can I help you today?

README

Complete guide to using gpt-5-6-sol

Scale Ambitious AI Products with GPT-5.6 API on Kie.ai

image
image
image
image
image
image
image
Comparison Area
GPT-5.6 Sol
GPT-5.6 Terra
GPT-5.6 Luna
Official Positioning
Flagship frontier model
Balanced lower-cost model for everyday work
Fastest and most affordable model
Capability Direction
Maximum intelligence and efficiency
Strong performance with practical cost efficiency
Fast execution for high-volume workloads
Core Strengths
Advanced coding, knowledge work, computer use, cybersecurity, science, and complex reasoning
Everyday coding, analysis, professional work, and balanced production tasks
Frequent requests, scalable processing, and cost-sensitive workloads
Agents’ Last Exam
52.70%
50.40%
50.30%
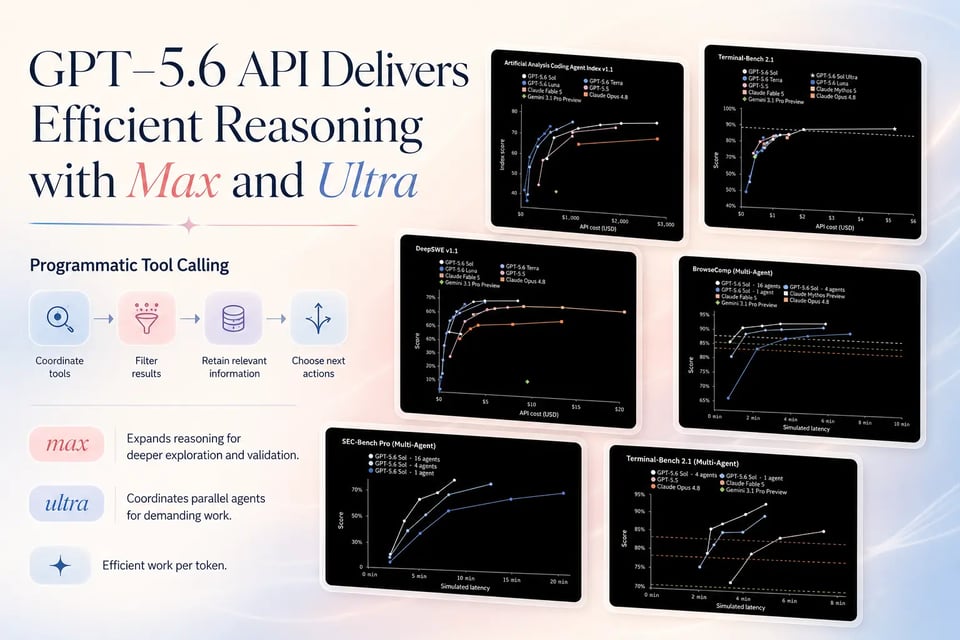
Artificial Analysis Coding Agent Index v1.1
80
77.4
74.6
SWE-Bench Pro
64.60%
63.40%
62.70%
Terminal-Bench 2.1
88.80%
87.40%
84.70%
BrowseComp
90.40%
87.50%
83.30%
OSWorld 2.0
62.60%
50.20%
45.60%
SEC-Bench Pro
71.20%
57.70%
48.90%
GeneBench Pro
28.70%
23.30%
10.80%
MRCR v2, 256K–512K
91.50%
89.60%
41.30%
OpenAI Official Input Price
$5 per 1M tokens
$2.50 per 1M tokens
$1 per 1M tokens
OpenAI Official Output Price
$30 per 1M tokens
$15 per 1M tokens
$6 per 1M tokens
Evaluation Area
Benchmark
GPT-5.6 Sol
GPT-5.5
Claude Mythos 5
Claude Fable 5
Claude Opus 4.8
Gemini 3.1 Pro Preview
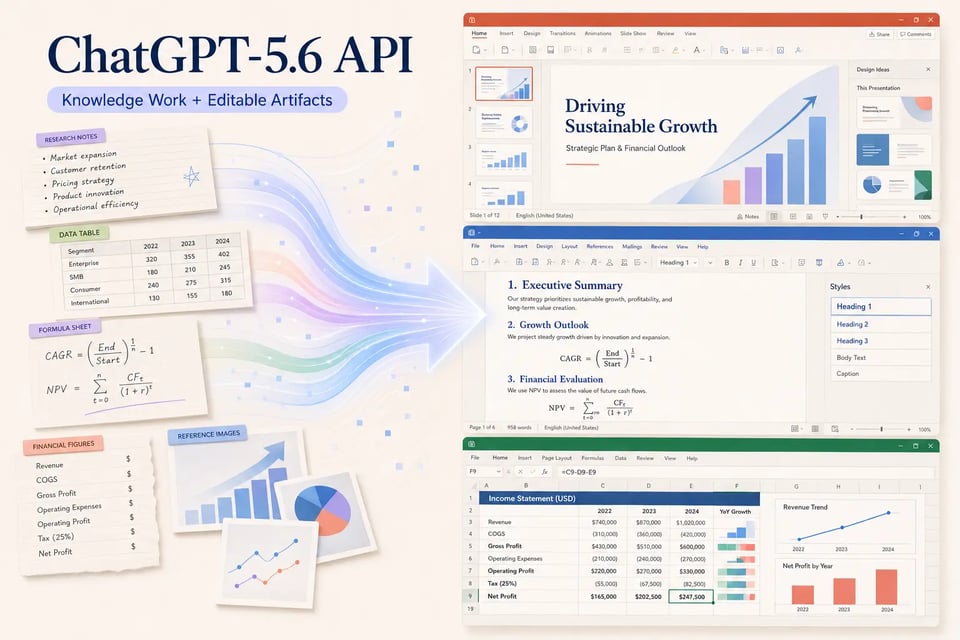
Professional Work
Agents’ Last Exam
52.70%
46.90%
—
40.50%
45.20%
32.10%
Professional Work
GDPval-AA v2
1,747.8 Elo
1,493.7 Elo
—
1,759.6 Elo
1,600.1 Elo
962.3 Elo
General Intelligence
Artificial Analysis Intelligence Index v4.1
58.9
54.8
—
59.9
55.7
46.5
Agentic Coding
Artificial Analysis Coding Agent Index v1.1
80
76.4
—
77.2
72.5
42.7
Software Engineering
SWE-Bench Pro
64.60%
59.40%
80.30%
80.00%
69.20%
54.20%
Long-Horizon Engineering
DeepSWE v1.1
72.70%
67.00%
—
69.70%
59.00%
11.80%
Terminal Coding
Terminal-Bench 2.1
88.80%
85.60%
88.00%
83.10%
78.90%
70.70%
Agentic Browsing
BrowseComp
90.40%
84.40%
88.00%
—
84.30%
85.90%
Scientific Reasoning
GPQA Diamond
94.60%
93.60%
94.10%
92.60%
92.00%
94.30%
Advanced Mathematics
FrontierMath Tier 1–3 v2
89.00%
85.30%
—
87.00%
80.00%
59.60%
Tool Use
Toolathlon
58.00%
55.60%
61.70%
61.70%
59.90%
48.80%
image
image
image
image