Automatically append previous messages to maintain multi-turn context. May increase token usage.
How can I help you today?
README
Complete guide to using deepseek-v4-1-flash
DeepSeek-V4.1-Flash API for Fast and Efficient Multimodal Reasoning
Use DeepSeek-V4.1-Flash API for responsive reasoning, native visual understanding, coding, and agentic workflows with an architecture built for efficient inference and high throughput.
Key Features of DeepSeek-V4.1-Flash API
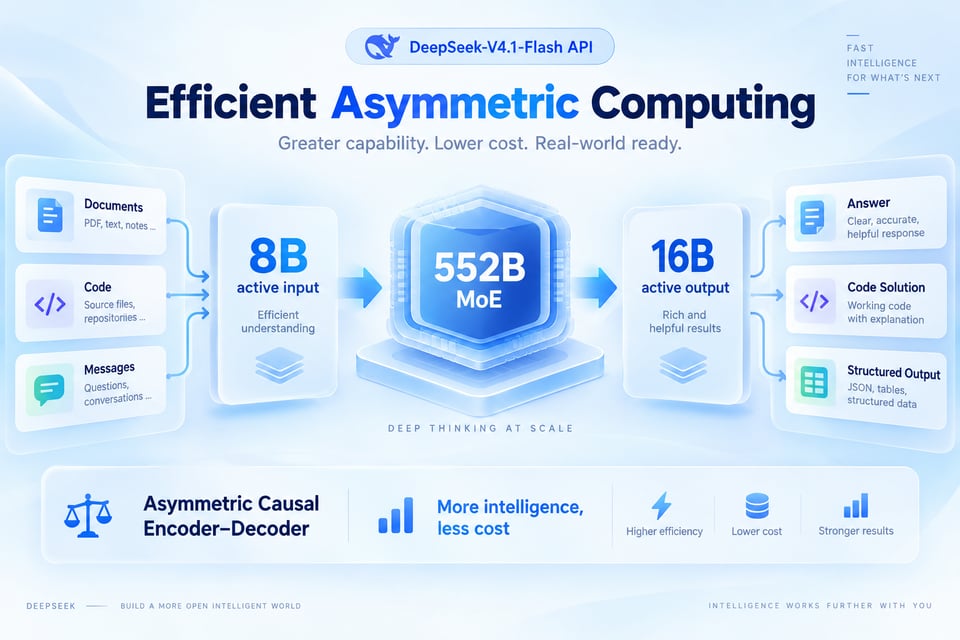
DeepSeek-V4.1-Flash API Brings Efficient Asymmetric Computing
Built on a 552B-parameter Mixture-of-Experts backbone, DeepSeek-V4.1-Flash API uses a new Causal Encoder–Decoder architecture with asymmetric computation across input and output. The model activates about 8B parameters per token during input processing and 16B during output generation, reducing active computation relative to its total model capacity.
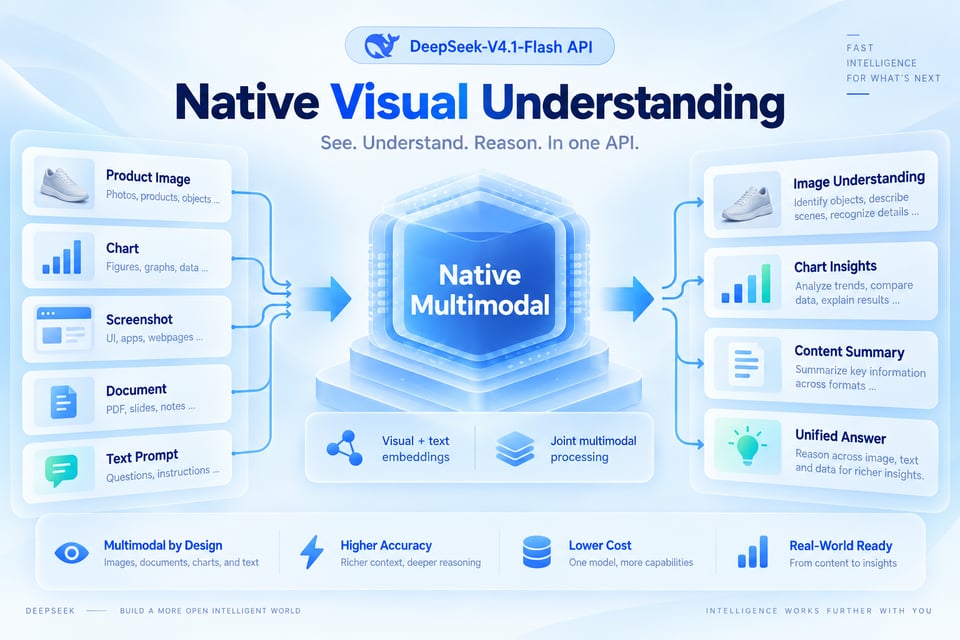
Native Visual Understanding Comes with DeepSeek V4.1 Flash API
Rather than treating vision as a separate add-on, DeepSeek V4.1 Flash API natively processes images and text within the same multimodal architecture. Visual embeddings and text embeddings are jointly processed from language-model pretraining, giving the model built-in support for image-based understanding alongside textual reasoning.
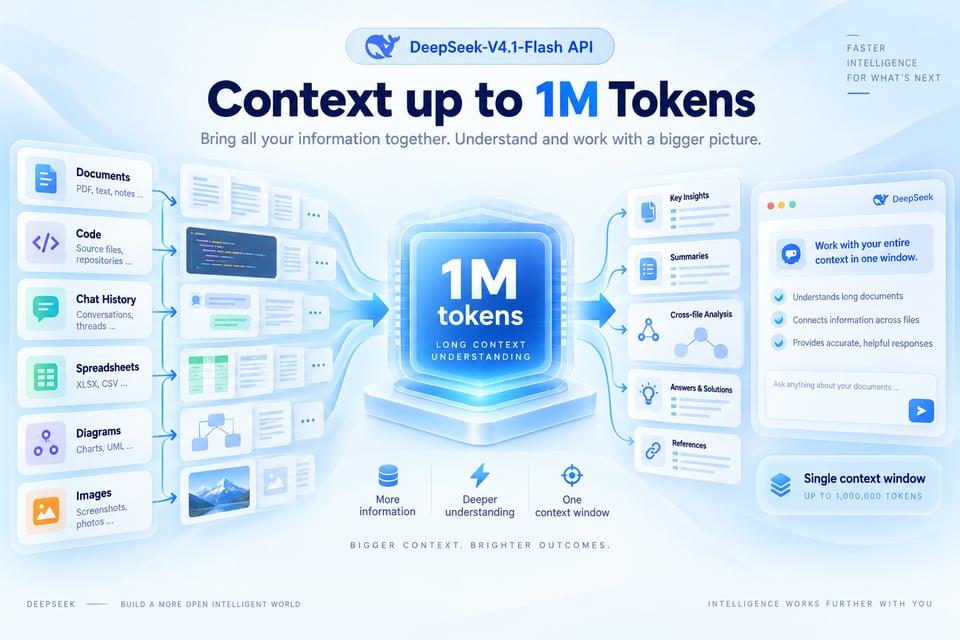
DeepSeek 4.1 Flash API Extends Context to One Million Tokens
For information-heavy workloads, DeepSeek 4.1 Flash API supports context lengths of up to one million tokens. This expanded context capacity allows the model to process substantially larger bodies of text, code, conversation history, and multimodal information within a single context window.
A Compressed KV Cache Makes DeepSeek API Workloads More Efficient
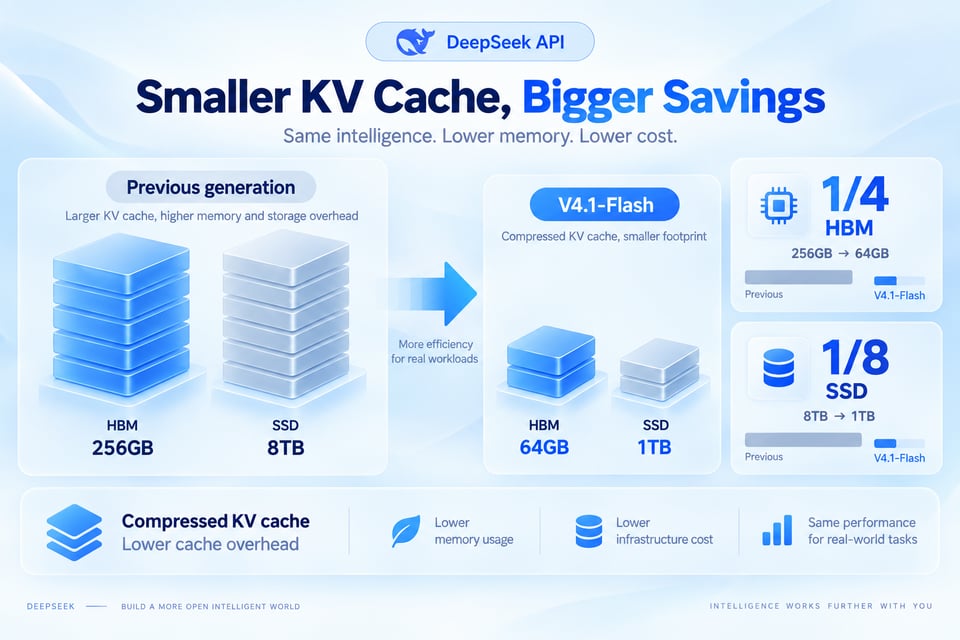
DeepSeek API applications using V4.1-Flash benefit from a substantially smaller persistent KV cache than the previous V4-Flash generation. DeepSeek reports that the new design requires about one-quarter of the HBM and one-eighth of the SSD storage, reducing cache overhead for workloads that process or reuse large contexts.
Built for Higher Throughput, DeepSeek-V4.1-Flash API Fits Agentic Workloads
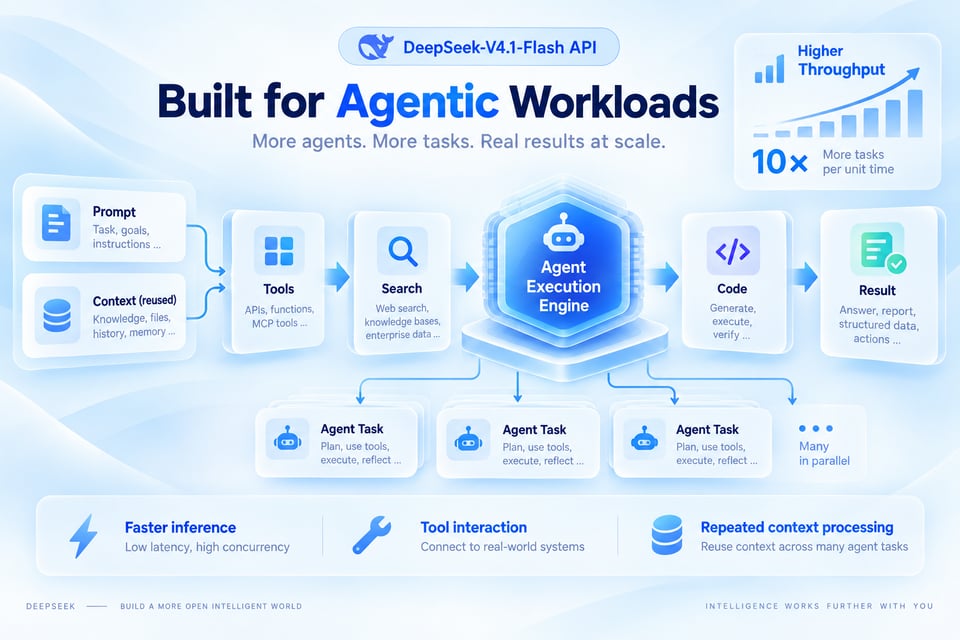
DeepSeek-V4.1-Flash API is designed for faster inference and higher throughput, while its Causal Encoder–Decoder architecture improves efficiency for input-heavy agentic workloads. These characteristics make it particularly relevant to applications that involve long prompts, repeated context processing, tool interaction, coding, and multi-step model execution.
How DeepSeek-V4.1-Flash Performs Across Demanding Tasks
DeepSeek-V4.1-Flash benchmark results reflect improvements across a wide mix of demanding workloads rather than a single capability area. Compared with the earlier V4-Flash generation, the model posts stronger results in coding, repository-level software engineering, terminal tasks, automation, and tool-assisted reasoning, while remaining competitive on broader reasoning and multimodal evaluations. The table below shows how DeepSeek-V4.1-Flash performs across the full benchmark set alongside other leading models.
| Benchmarks | DeepSeek V4.1-Flash | DeepSeek V4-Pro 0813 | DeepSeek V4-Flash 0731 | GLM 5.3 | Kimi K3 | GPT 5.6-Sol | Claude Opus 5 |
|---|---|---|---|---|---|---|---|
| GPQA Diamond | 90.9 | 92.4 | 89.9 | 88.1 | 92.9 | 94.1 | 93.4 |
| HLE | 36.8 (39.1*) | 42.7* | 37.8* | 42.0* | 43.5 | 44.5 | 56.3 |
| Codeforces (Rating) | 3471 | 3348 | 3289 | — | — | — | — |
| MathArena Apex | 65.6 | 65.3 | 58.6 | — | 65.6 | — | — |
| Terminal-Bench 2.1 | 90.6 | 87.9 | 82.7 | 88.2 | 88.3 | 88.8 | 89.1 |
| Terminal-Bench 3.0 | 30.0 | 11.8 | 7.6 | 28.3 | 17.7 | 34.4 | 43.3 |
| Terminal-Bench 4.0 | 31.2 | 12.4 | 7.0 | 37.9 | 12.6 | 39.9 | 51.8 |
| DeepSWE v1.1 | 74.2 | 62.7 | 54.4 | 66.9 | 67.5 | 73.0 | 74.0 |
| ProgramBench | 20.3 | 15.5 | — | 19.0 | 17.5 | 23.0 | 37.0 |
| NL2Repo-Bench | 65.4 | 61.5 | 54.2 | 58.0 | 58.0 | 56.8 | 75.3 |
| CyberGym | 88.1 | 83.3 | 76.7 | 84.5 | 80.0 | 84.5 | — |
| SEC-Bench Pro | 62.8 | 56.4 | 30.9 | — | — | 74.3 | — |
| ExploitGym | 15.3 | 5.4 | 1.8 | 15.0 | — | 33.7 | 22.1 |
| HLE (w/tools) | 63.9 | 60.0 | 51.5 | 62.5 | 59.8 | — | 63.6 |
| Automation-Bench | 54.8 | 43.2 | 37.7 | 48.8 | 46.7 | 45.8 | 50.3 |
| Agents' Last Exam | 31.8 | 25.7 | 25.2 | 28.5 | 27.6 | 26.7 | 28.6 |
| Chartography (w/tools) | 78.9 | — | — | — | 68.1 | 79.9 | 84.0 |
| BabyVision (w/tools) | 89.6 | — | — | — | 85.7 | 88.9 | 94.1 |
| ZeroBench-main (w/tools) | 49.0 | — | — | — | 41.0 | 53.0 | 52.0 |
| Note | * Denotes the text-only subset of HLE. |
How to Get Started with DeepSeek-V4.1-Flash API
You can move from account setup to testing and deployment in three straightforward steps. Start by getting your API key, validate the model in the Playground, then connect DeepSeek-V4.1-Flash API to your own application or workflow.
1. Sign Up on EMix.ai and Get Your DeepSeek-V4.1-Flash API Key
2. Test DeepSeek V4.1 Flash API in the Playground
3. Deploy DeepSeek 4.1 Flash API in Your Application
What Can You Build with DeepSeek-V4.1-Flash API
Build Coding Assistants with DeepSeek-V4.1-Flash API
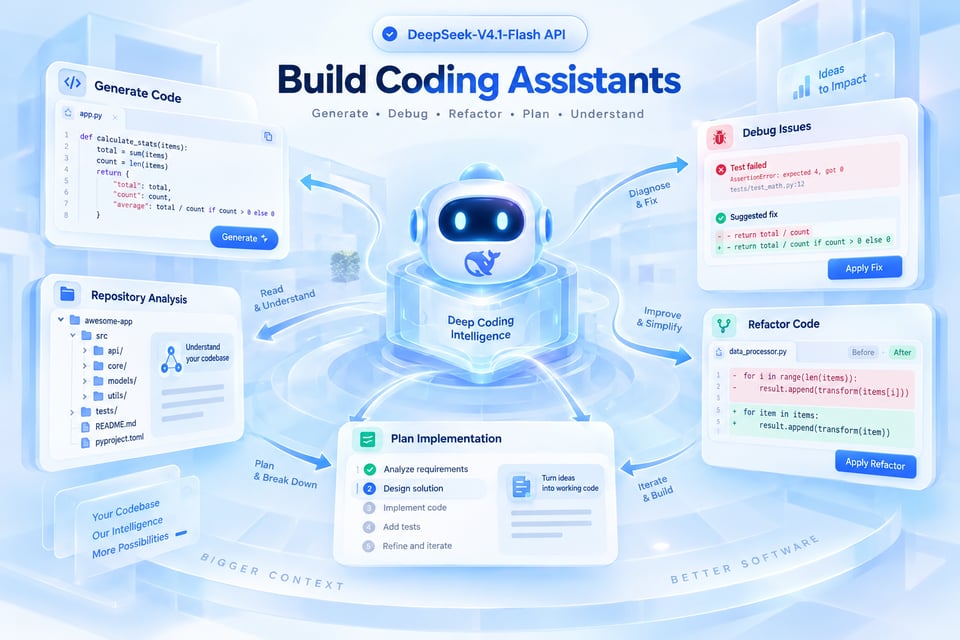
DeepSeek-V4.1-Flash API can support code generation, debugging, refactoring, implementation planning, and repository-level analysis. Developers can use it to build coding assistants that work across larger code contexts and handle more involved software engineering tasks from planning through iterative development.
Create AI Agents with DeepSeek V4.1 Flash API
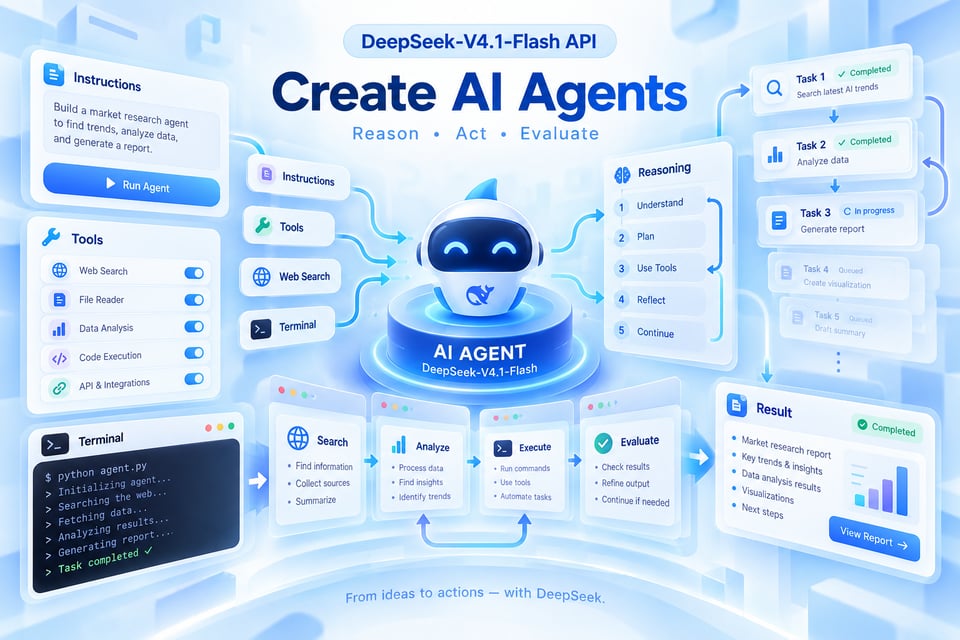
DeepSeek V4.1 Flash API fits agentic workflows that involve repeated reasoning, tool interaction, terminal operations, and multi-step execution. It can support assistants that interpret instructions, take actions, evaluate intermediate results, and continue working across longer task sequences.
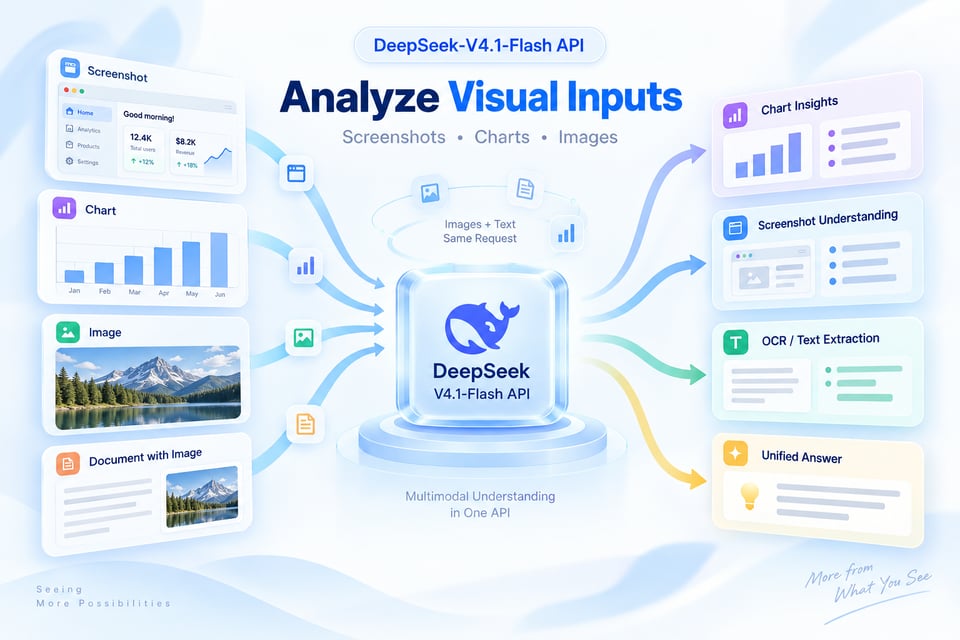
Analyze Visual Inputs with DeepSeek 4.1 Flash API
DeepSeek 4.1 Flash API supports native multimodal understanding for images alongside text. Developers can use it to build workflows that interpret screenshots, read text from images, analyze charts, and reason about other visual content within the same request.
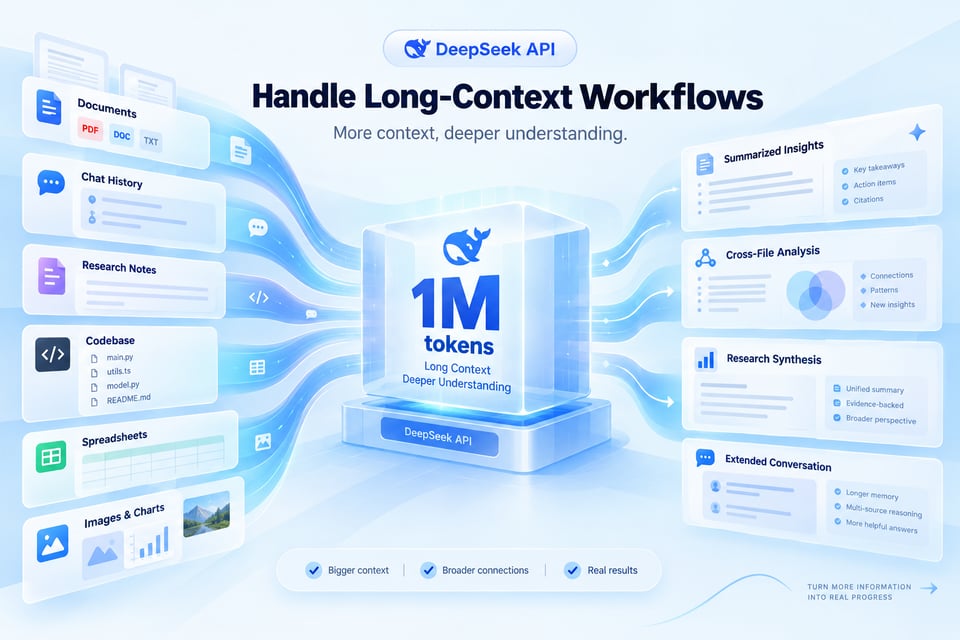
Handle Long-Context Workflows with DeepSeek API
DeepSeek API can support long-context tasks such as extended conversations, research workflows, large codebase understanding, and other information-heavy tasks with V4.1-Flash. Its expanded context capacity helps keep more relevant information available across complex workflows without constantly breaking inputs into smaller pieces.
Why Choose Kie.ai for DeepSeek-V4.1-Flash API Integration
Get More Value from DeepSeek-V4.1-Flash API Pricing
Kie.ai offers cost-effective DeepSeek-V4.1-Flash API Pricing for developers who want to control model costs while scaling real applications. Whether you are testing early ideas or handling larger workloads, the pricing structure is designed to make ongoing API usage more manageable.
Follow Complete DeepSeek-V4.1-Flash API Documentation
Detailed DeepSeek-V4.1-Flash API documentation helps developers move from setup to integration with less friction. You can find the information needed for authentication, request configuration, supported inputs, response handling, and practical implementation in one place.
Get 24/7 Support for DeepSeek 4.1 Flash API
When integration or usage issues come up, Kie.ai provides 24/7 service support for DeepSeek 4.1 Flash API users. Continuous assistance can help reduce delays during testing, deployment, and ongoing application development.
Explore More Popular Models Beyond DeepSeek API
Kie.ai also provides access to other popular model APIs alongside DeepSeek API, giving developers more flexibility when different tasks require different capabilities. You can test and integrate multiple leading models without rebuilding your entire API workflow around separate platforms.