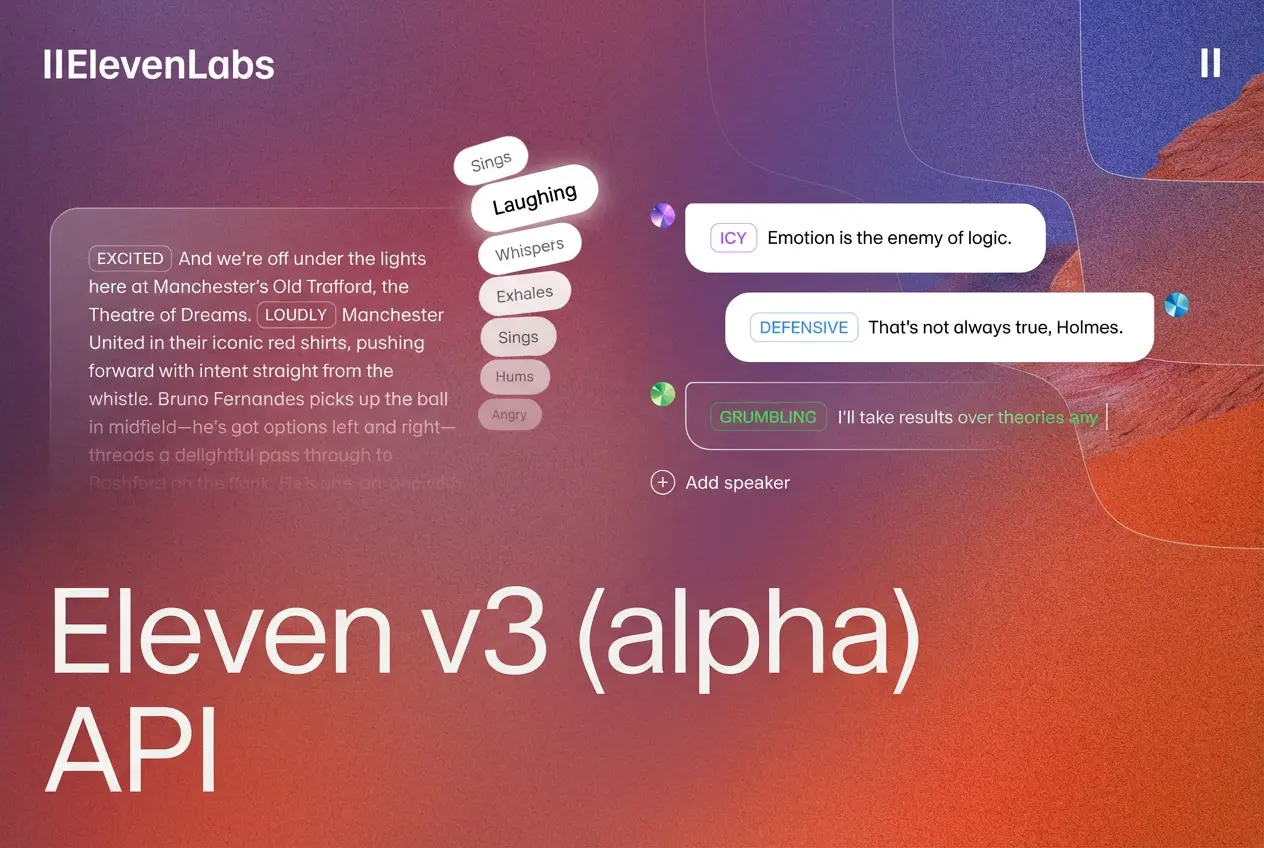
ElevenLabs v3 ermöglicht lebensechte, mehrsprachige Dialoge mittels Steuerung per Audio-Tags, Multi-Speaker-Support und natürlicher Betonung – ideal für dialogorientierte Anwendungen, Storytelling-Tools und immersive Spracherlebnisse.

Pricing: ElevenLabs Text-to-Speech V3: 14 credits per 1,000 characters (≈ $0.07) ~ 30% cheaper than fal pricing. High-tier top-ups (+10% bonus) bring effective pricing down to ≈ ($0.063) per 1,000 characters
Input
0
No items yet. Click Add to start.

Determines how stable the voice is and the randomness between each generation.

Select description

Output
output typeaudio

README

Complete guide to using elevenlabs/text-to-dialogue-v3

Kostengünstige Eleven v3 API für mehrsprachige Dialoggenerierung

Original image

Eleven V3 (Alpha) API introduces inline audio tags that allow fine-grained control over tone, emotion, and non-verbal reactions directly within the text. Through the ElevenLabs V3 API, creators can guide delivery with cues such as whispering, laughter, hesitation, or emphasis, making speech feel intentional and expressive rather than mechanically generated.

With Text to Dialogue, the ElevenLabs V3 API enables multi-speaker conversations that feel natural in timing, pacing, and interaction. Eleven V3 API supports realistic turn-taking and interruptions, allowing teams to create flowing conversations for podcasts, games, storytelling, and dialogue-heavy audio experiences without manually stitching together separate voice tracks.

The Eleven V3 API supports expressive speech generation across more than 70 languages, covering high-demand global markets. Through the ElevenLabs V3 API, both Text to Speech and Text to Dialogue workflows can maintain nuance, prosody, and emotional delivery across languages, making it suitable for multilingual products and international audiences.

ElevenLabs V3 API demonstrates deeper understanding of text input, resulting in improved stress, cadence, and overall expressiveness for Text to Speech generation. Eleven V3 (Alpha) API is better able to interpret context and intent from scripts, allowing generated speech to carry more natural rhythm and emotional continuity across longer passages.

  • 01
  • 02
  • 03
  • 04
  • 05
  • 5.0/ 5
    33,854 ratings
    Tap a star to rate