How GPT-5.6 Sol Compares with Leading Frontier Models
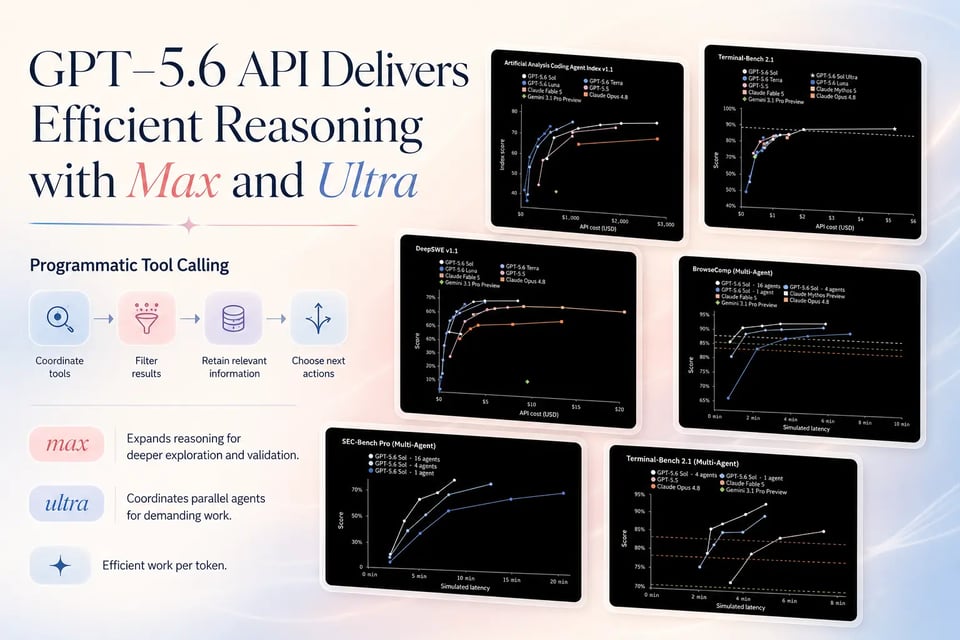
GPT-5.6 Sol competes across professional reasoning, agentic coding, terminal work, browsing, mathematics, and general intelligence rather than optimizing for a single evaluation category. The comparison below uses results published in OpenAI’s general-availability release. A dash indicates that no result was reported for that model in the corresponding evaluation, while real performance can vary with reasoning effort, tools, prompts, and evaluation settings. GPT-5.6 Sol leads this selection on Agents’ Last Exam, the Coding Agent Index, DeepSWE, Terminal-Bench 2.1, BrowseComp, GPQA Diamond, and FrontierMath Tier 1–3. Claude models remain ahead on certain evaluations, including SWE-Bench Pro, GDPval-AA v2, and Toolathlon, showing that model selection should account for the specific task rather than relying on one aggregate score.