Seedance 2.5 on KIE is ByteDance’s upgraded AI video model, built for longer, more controllable video generation. It supports up to 30-second videos, multimodal references, precise editing, and improved consistency for more cinematic and production-ready creative workflows.
Wan3.0 is Alibaba’s next-generation all-in-one video generation model built for multimodal creation. It supports text, image, video, audio, and structured references to produce more consistent, realistic, and controllable video content with enhanced storytelling and editing capabilities.
Seedance 2.0 on KIE is a multimodal Al video model by ByteDance, optimized for fast and realistic video generation. It supports high-quality virtual human video creation with strong multi-shot consistency, enabling more lifelike and cinematic outputs across scenes.
GPT Image 2 is OpenAI’s next-gen image model built for stronger photorealism, cleaner image editing, sharper text rendering, and more polished product photography. Designed for more advanced visual workflows, it pushes image generation beyond basic text-to-image output and into higher-quality creative, commercial, and design-ready use cases.
Meet Nano Banana 2, Google’s Gemini 3.1 Flash Image model, now available via Kie AI API. Built for developers, it combines lightning-fast speed with Pro-level quality, accurate text rendering, strong character consistency, and scalable image generation and editing workflows.
Grok 4.6 is xAI’s latest frontier AI model, designed to enhance long-running agents, advanced reasoning, coding intelligence, and interactive AI experiences. Building on Grok 4.5, it delivers improved performance for complex multi-step tasks, knowledge work, software engineering, and creative applications.
Google’s efficient text-to-speech model built for low-latency, high-throughput voice generation. Gemini 3.8 Flash-Lite TTS supports natural speech across 101 languages, voice replication, multi-speaker audio, and long-form generation, making it ideal for voice agents and high-volume TTS workflows.
Google’s flagship creative text-to-speech model for high-fidelity, expressive voice generation. Gemini 3.8 Flash TTS supports natural-language voice design, voice cloning from around 30s of authorized audio, multi-speaker dialogue, and speech generation across 130 languages.
Gemini 2.5 Pro Preview TTS is Google’s premium text-to-speech model designed for studio-quality, high-fidelity audio generation. It enables developers to create realistic AI voices with natural language instructions, expressive speech, and long-form audio capabilities.
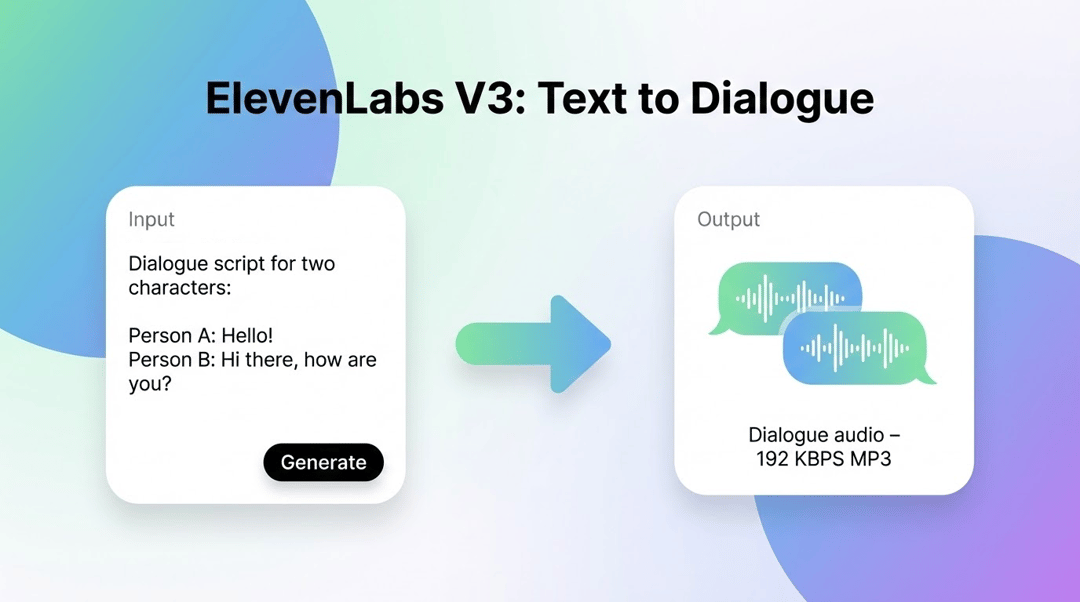

AI音声を生成する音声合成API
スケーラブルな音声合成APIで、自然なAI音声体験を構築。ElevenLabsを含む複数のAI音声モデルにアクセスし、無料でのテストと高速な統合が可能です。
Kie.ai Text to Speech APIの主な機能
自然なAI音声でテキストを読み上げる技術
自然なトーン、正確な発音、人間のような表現を実現する強力なAI音声合成APIで、自然な音声をリアルに生成できます。動画、アプリ、デジタル製品など、さまざまなシーンで魅力的で自然な音声コンテンツを作成しましょう。
リアルタイムアプリケーション向けの高速なテキスト読み上げAPI
低遅延のテキスト読み上げAPIで、ユーザーに快適な音声体験を提供します。AIアシスタント、チャットボット、カスタマーサポートシステム、インタラクティブアプリケーション向けのリアルタイムテキストから音声へのAPIワークフローをサポートします。
Kie.aiテキスト読み上げAPIの使い方ガイド
ステップ1:テキスト読み上げAPIモデルを確認・選択
利用可能なテキスト読み上げAPIモデルを確認し、音声品質、速度、言語サポート、スピーキングスタイルを比較して、製品のニーズに合ったAIテキスト読み上げAPIを選択できます。
ステップ2:無料のテキスト読み上げAPIクレジットを使ってテストしてみましょう
オンラインプレイグラウンドと無料のテキスト読み上げAPIクレジットを使用してサンプル音声を生成できます。統合前にTTS APIの出力品質を素早く検証できます。
ステップ3:テキスト読み上げAPIキーを取得する
APIキーを取得し、統合環境を準備します。シンプルなセットアップと開発者フレンドリーなアクセスで、テキストから音声へのAPIワークフローの構築を始めることが可能です。

ステップ4:テキストを送信してAIによる音声を生成する
テキスト読み上げAPIリクエストを送信し、即座に音声に変換します。AI音声によるテキスト読み上げ出力を、アプリ、コンテンツプラットフォーム、アシスタント、自動化ツールなどに活用できます。

Kie.aiのテキスト読み上げAPIを選ぶ理由
1つの統合で複数のテキスト読み上げAPIモデルにアクセスできます
高速テスト用の無料テキスト読み上げAPIクレジットを提供
コスト効率が高く、高速なAIテキスト読み上げAPI
明確なドキュメントで、簡単にテキストから音声生成APIを統合できます
SaaSおよびアプリケーション向けのテキスト読み上げAPIの実際の利用例
動画やコンテンツ制作に最適なAI音声読み上げ
テキストから音声変換API(TTS API)を使って、自然なAI音声を素早く生成できます。マーケティング動画、チュートリアル、ポッドキャスト、短編コンテンツ、ソーシャルメディア制作に活用し、手動での録音なしでAI音声コンテンツを迅速に作成できます。
AIアシスタントやチャットボット向けのTTS API
自然で応答性の高い音声出力で、会話機能を実現できます。仮想アシスタント、カスタマーサポートシステム、チャットアプリケーションにAIテキストから音声変換APIのワークフローを追加できます。
学習用プラットフォーム向けのテキストから音声変換API
スケーラブルなテキストから音声変換APIで、学習内容を音声に変換します。オンライン講座、言語学習アプリ、教育プラットフォーム向けに、AI音声によるテキスト読み上げ体験を構築できます。
アクセシビリティ製品向けのAI音声読み上げ機能
AIテキストから音声変換APIで、文章をより読みやすくします。記事、ウェブサイト、モバイルアプリ、デジタル製品のアクセシブルな体験を音声出力で実現できます。
プロトタイプ開発向けの無料テキストから音声変換API
無料のテキストから音声変換APIでテストを開始し、本番環境での音声機能の検証が可能です。新製品やMVP開発のためのAI音声ワークフローを迅速に構築・テストできます。
24/7 Support for Text to Speech API Developers
Get support anytime for text to speech API integration, workflow questions, and technical issues. Build and scale AI voice text to speech applications with confidence.
Kie.ai テキスト読み上げAPIに関するよくある質問とその答え
テキスト読み上げAPIとは何か?
テキスト読み上げAPIは、APIリクエストを使って文章を自然な音声に変換する仕組みです。開発者はこのAPIを使って、アプリやウェブサイト、AI製品に音声機能を追加できます。
Kie.aiは無料のテキスト読み上げAPIを提供していますか?
はい。Kie.aiはテスト用に無料の利用枠を提供しています。開発者はAIテキスト読み上げAPIのワークフローを試し、本番環境への移行前に音声品質を評価できます。
テキスト読み上げAPIをアプリケーションに統合する方法は?
APIキーを作成し、APIエンドポイントにテキストを送信して音声出力を取得し、それをアプリケーションのワークフローに組み込むことで、テキスト読み上げAPIを統合できます。詳細な実装方法については、APIドキュメントもご参照ください。
Kie.aiはElevenLabsのテキスト読み上げ機能を提供していますか?
はい。Kie.aiはElevenLabsのテキスト読み上げ機能へのアクセスを提供し、さらに多くのAI音声モデルを追加しています。新しいモデルが追加されるたびに、より多くの音声オプションや機能が利用できるようになります。
テキスト読み上げAPIがよく使われる製品にはどのようなものがありますか?
テキスト読み上げAPIは、AIアシスタント、チャットボット、教育プラットフォーム、アクセシビリティツール、コンテンツ作成アプリ、音声対応のSaaS製品など、幅広く使われています。