Seedance 2.5 on KIE is ByteDance’s upgraded AI video model, built for longer, more controllable video generation. It supports up to 30-second videos, multimodal references, precise editing, and improved consistency for more cinematic and production-ready creative workflows.
Wan3.0 is Alibaba’s next-generation all-in-one video generation model built for multimodal creation. It supports text, image, video, audio, and structured references to produce more consistent, realistic, and controllable video content with enhanced storytelling and editing capabilities.
Seedance 2.0 on KIE is a multimodal Al video model by ByteDance, optimized for fast and realistic video generation. It supports high-quality virtual human video creation with strong multi-shot consistency, enabling more lifelike and cinematic outputs across scenes.
GPT Image 2 is OpenAI’s next-gen image model built for stronger photorealism, cleaner image editing, sharper text rendering, and more polished product photography. Designed for more advanced visual workflows, it pushes image generation beyond basic text-to-image output and into higher-quality creative, commercial, and design-ready use cases.
Meet Nano Banana 2, Google’s Gemini 3.1 Flash Image model, now available via Kie AI API. Built for developers, it combines lightning-fast speed with Pro-level quality, accurate text rendering, strong character consistency, and scalable image generation and editing workflows.
Grok 4.6 is xAI’s latest frontier AI model, designed to enhance long-running agents, advanced reasoning, coding intelligence, and interactive AI experiences. Building on Grok 4.5, it delivers improved performance for complex multi-step tasks, knowledge work, software engineering, and creative applications.
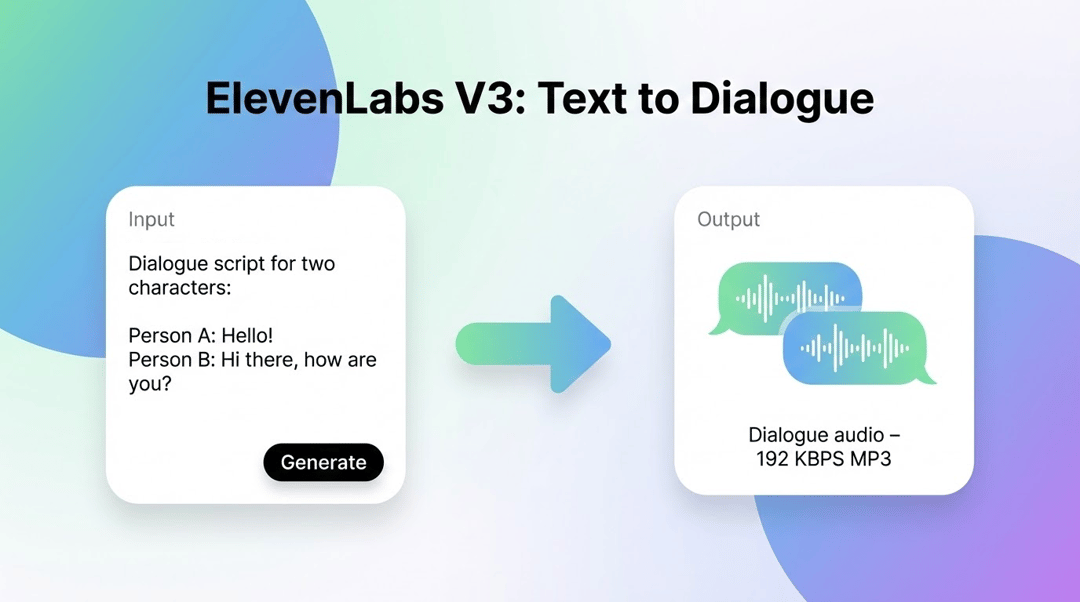

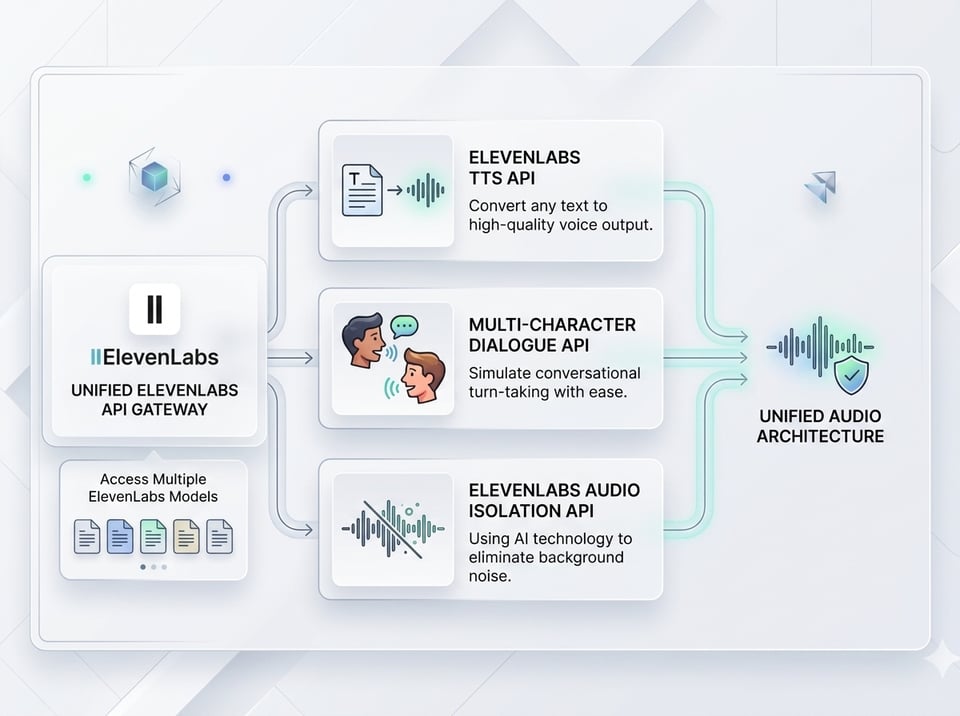
1つの場所ですべてのElevenLabs APIを統合的に利用できる
マルチリンガルv2、Text-to-Dialogue v3、Audio Isolation APIなど、ElevenLabs APIモデルを1つのプラットフォームで無料でテストし、スケーラブルに統合できるようになります。
ElevenLabs Voice API モデルによるAI音声生成・編集機能
高忠実度の AI 音声生成のための ElevenLabs TTS API
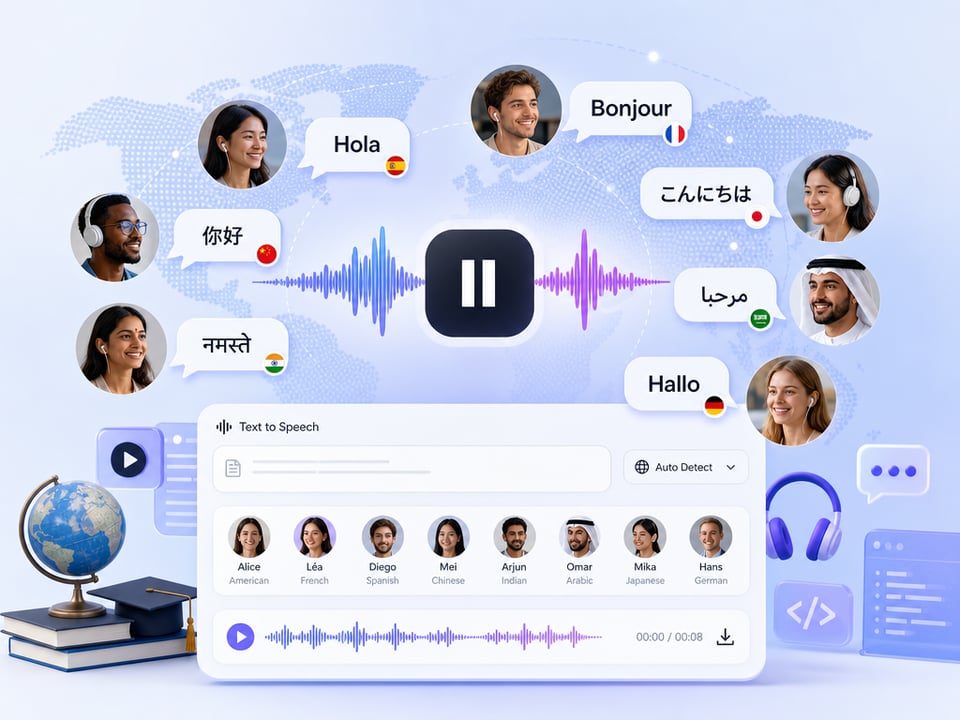
ElevenLabs TTS API は、専用のサブモデルを通じて多様なテキストから音声へのワークフローを提供します。マルチリンガル V2 API は、正確なアクセントを保ちながら自然な音声に変換し、低遅延の Turbo V2.5 API は言語コードを明示的に指定することで、グローバルなアクセシビリティを実現します。
複数の声で会話を行うための ElevenLabs Voice V3 API
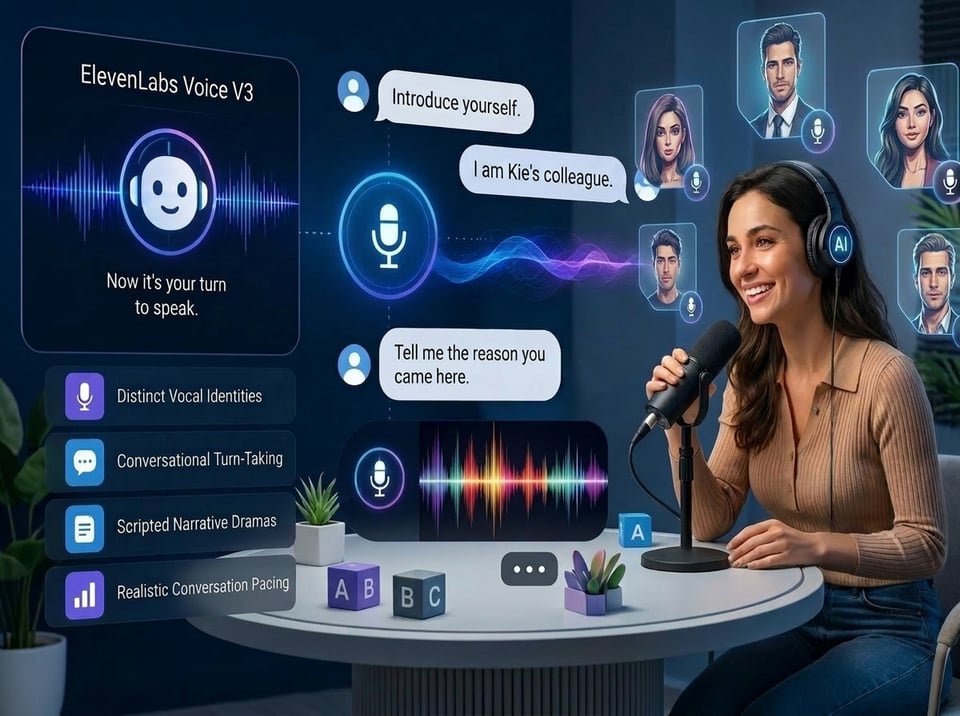
ElevenLabs Voice V3 API は、70以上の言語に対応したマルチスピーカー対応のダイアログ合成機能により、スクリプトから音声への自動化を効率化します。インライン音声タグをネイティブに解釈できるため、開発者は笑い、ささやき、抑揚、強調などの非言語的表現をプログラムで制御し、音声の演出を柔軟に実現できます。

プログラムによる音声分離API
ElevenLabs Voice Isolation API は、高度なニューラル周波数分離技術を用い、ノイズや破損した音声から高品質な人間の声を抽出する技術です。インタビュー、ポッドキャスト、ライブ配信に最適化されており、マイクのヒス音、交通音、背景の会話、重複する音楽などを効果的に除去します。
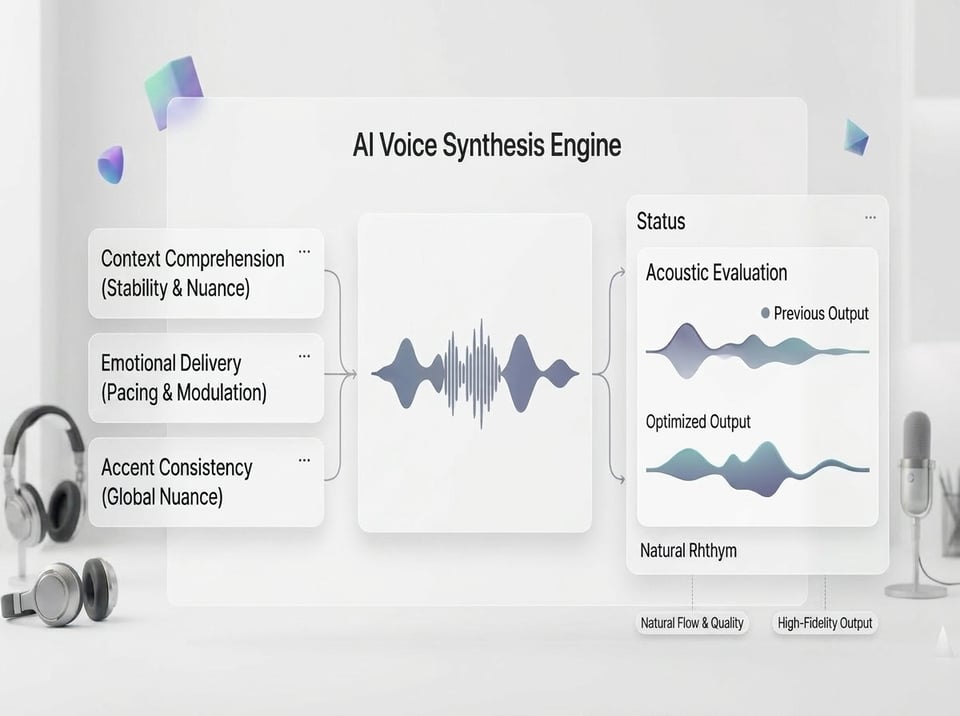
Media Format Compatibility & ElevenLabs AI API Payloads
Process standard UTF-8 text strings, structured JSON narrative arrays, and external media files in .mp3, .wav, .mp4, or .mov formats within a single, streamlined Asynchronous Audio Task API pipeline. Build scalable audio deal with tools and SaaS applications capable of parsing complex audio layouts generation loops inside one robust AI ecosystem.
ElevenLabs AI APIへのアクセスにおいて、なぜKie.aiを選ぶのか
登録後無料トライアルによるテスト機能
アカウント作成時に無料テストクレジットとインタラクティブなサンドボックス環境を提供しています。この環境により、開発者はモデルパラメータの評価、エンドポイントのレイテンシーテスト、リクエスト・レスポンスの構造確認が可能となり、本番環境へのデプロイ前に十分な検証ができます。
利用量に応じた料金制
このサービスは、標準的な開発者利用に合わせた「利用量に応じた課金方式」で運用されています。この仕組みにより、テキストから音声への変換、会話スクリプトの実行、ボイス分離パイプラインなどにおけるリソース使用量を正確に追跡でき、チームはアプリケーションの稼働量に比例してコンピューティングコストをスケールアップすることが可能です。
24時間365日対応の技術サポートおよびインフラ支援
技術的なモニタリングおよび開発者サポートは毎日24時間365日対応可能です。エンジニアリングチームはAPI統合やペイロード最適化、接続タイムアウト、高并发性ルーティング調整に関する技術サポートを提供し、アプリケーションの稼働率を維持するお手伝いをします。
ElevenLabs API を Kie.ai で活用する方法
ステップ1:適切なElevenLabs APIエンドポイントを選択する
ターゲットとなるワークフローに合った専用エンドポイントを選択してください。ElevenLabs TTS APIで単一ボイスのナレーションを実現し、構造化されたマルチスピーカーダイアログスクリプトにはElevenLabs Voice V3 APIに切り替えるか、バックグラウンドノイズの抑制やボイストレーニング後のクリーニング処理にはVoice Isolation APIを活用できます。
ステップ2: オンラインプレイグラウンドで音声モデルを試してみる
Kie.aiの開発者プレイグラウンドを使用して、統合する前に選択した音声モデルを試してみましょう。カスタムテキストを入力し、リアルタイムの音声プロパティを評価し、無料トライアルクレジットを使ってAPIのレスポンス形式を確認してから、本番デプロイ用のスクリプトを記述してください。
ステップ3: APIキーを取得し、技術ドキュメントを確認する
ダッシュボード内で安全なAPIアクセスキーを生成し、プラットフォーム統合型の技術ドキュメントを確認してください。リクエストのペイロード形式、クレジットの料金スケジュール、安定性やsimilarity_boostなどの調整項目など、重要な設定項目を確認することで、デプロイ時の設定ボトルネックを最小限に抑えることができます。
ステップ4: パイプラインを業務フローに組み込む
柔軟なゲートウェイを本番環境、アプリケーションアーキテクチャ、または自動化されたコンテンツ作成ワークフローに接続します。一度の接続で複数のサービスを統合できるインターフェースを通じて、スケーラブルなAI音声ジェネレーター、レスポンシブなスクリプトリーダー、自動ポッドキャスト合成パイプライン、高度な音響隔離マイクロサービスを構築できます。
ElevenLabs APIで開発者が作成できるもの
オーディオブックを自動で出版するプラットフォーム
多言語対応の動画ローカライズ・吹き替えツール
映画制作・編集者向け – ElevenLabs Audio Isolation APIによる音声の分離処理
仮想のフルキャスト形式のポッドキャストプラットフォーム
What Developers Can Build With ElevenLabs API
Automated Audiobook Publishing Platforms
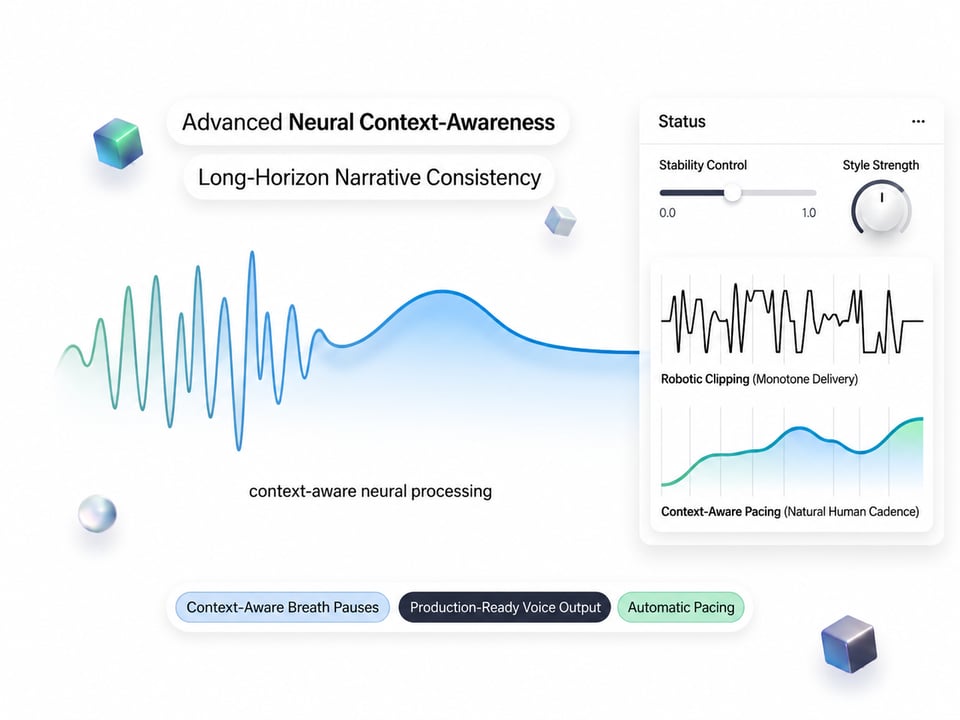
Developers can build long-form content deployment pipelines that ingest complete book manuscripts and output production-ready audio assets. Utilizing the ElevenLabs TTS API, these platforms convert massive text files into single-voice narrations with human-like breathing cadences, employing previous request IDs for continuous multi-chunk patching to maintain acoustic momentum across chapter boundaries.
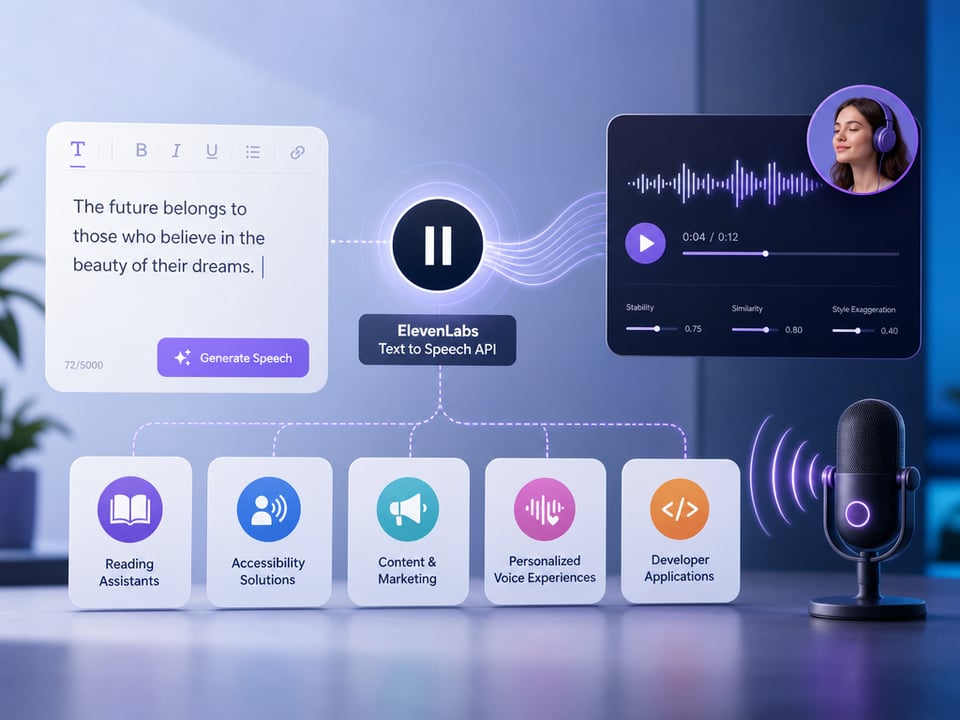
Global Video Localization and Dubbing Software
This application framework enables multi-market video adaptation by automating the voice-dubbing process for international distribution. By integrating the ElevenLabs TTS API (Multilingual V2), the system scales global video localization tools that translate text while preserving original speaker characteristics, regional accent nuances, and emotional profiles across different languages.
Filmmakers & Editors – Dialogue Polishing with ElevenLabs Audio Isolation API
Post-production teams and video editors can deploy automated audio cleaning pipelines to salvage compromised production audio directly from film sets or field recordings. Operating through the Voice Isolation API, this system allows filmmakers to upload dialogue clips from multi-format video containers up to 500MB, programmatically isolating raw human speech frequencies while filtering out severe wind noise, camera hums, and unpredictable environmental background chatter.

Virtual Full-Cast Podcast Platforms
This use case involves building automated podcast production networks that simulate multi-host roundtables, corporate panel discussions, or scripted narrative dramas. Powered by the ElevenLabs Voice V3 API, the system orchestrates multi-speaker dialogue setups that handle conversational turn-taking, distinct vocal identities, and realistic conversation pacing.
Frequently Asked Questions About ElevenLabs API
How does Kie.ai’s unified billing model assist enterprises with cost control?
Instead of purchasing separate credit pools from multiple providers for text-to-speech and audio isolation, Kie.ai utilizes a single, pay-as-you-go credit architecture. Enterprises manage one centralized account to allocate resources freely across all ElevenLabs endpoints, simplifying ROI tracking and precise computing cost calculations.
What technical safeguards does Kie.ai provide during high-concurrency requests or API error events?
Kie.ai provides 24/7 continuous engineering support to maintain production uptime. Technical teams are available around the clock to assist with high-concurrency rate limiting adjustments, network connection timeouts, and request payload configuration troubleshooting.
Can the ElevenLabs API handle multi-character conversational generation?
Yes. The ElevenLabs Voice V3 API parses structured script arrays within a single payload. It automatically generates multi-speaker dialogue with distinct voice IDs, natural turn-taking, and inline emotional tags without requiring manual audio file stitching.
Does the ElevenLabs API support background noise mitigation and vocal separation?
Yes. The Voice Isolation API uses a neural frequency separation engine to process multi-format audio and video files. It strips out microphone hiss, room reverb, traffic rumbles, and background music, leaving a purified human conversational track.
Is there a sandbox environment to test ElevenLabs models prior to deployment?
Yes. Kie.ai provides complimentary credits and an interactive browser-based playground upon registration. Developers can use this environment to test parameters, evaluate vocal outputs, and validate payload structures before writing production code.
Can the Voice Isolation API extract vocal layers from mixed musical tracks?
Yes. The Voice Isolation API processes complex audio files to isolate human vocals from backing music, sound effects, and instrumental tracks. While optimized for dialogue clarity and background noise mitigation, its frequency separation engine effectively decouples the vocal layer from mixed audio beds, outputting a purified voice track suitable for further editing or remixing.