Seedance 2.5 on KIE is ByteDance’s upgraded AI video model, built for longer, more controllable video generation. It supports up to 30-second videos, multimodal references, precise editing, and improved consistency for more cinematic and production-ready creative workflows.
Wan3.0 is Alibaba’s next-generation all-in-one video generation model built for multimodal creation. It supports text, image, video, audio, and structured references to produce more consistent, realistic, and controllable video content with enhanced storytelling and editing capabilities.
Seedance 2.0 on KIE is a multimodal Al video model by ByteDance, optimized for fast and realistic video generation. It supports high-quality virtual human video creation with strong multi-shot consistency, enabling more lifelike and cinematic outputs across scenes.
GPT Image 2 is OpenAI’s next-gen image model built for stronger photorealism, cleaner image editing, sharper text rendering, and more polished product photography. Designed for more advanced visual workflows, it pushes image generation beyond basic text-to-image output and into higher-quality creative, commercial, and design-ready use cases.
Meet Nano Banana 2, Google’s Gemini 3.1 Flash Image model, now available via Kie AI API. Built for developers, it combines lightning-fast speed with Pro-level quality, accurate text rendering, strong character consistency, and scalable image generation and editing workflows.
Grok 4.6 is xAI’s latest frontier AI model, designed to enhance long-running agents, advanced reasoning, coding intelligence, and interactive AI experiences. Building on Grok 4.5, it delivers improved performance for complex multi-step tasks, knowledge work, software engineering, and creative applications.

Tập hợp tất cả các API ElevenLabs: Multilingual v2, Text-to-Dialogue v3 & nhiều hơn tại một nơi
Truy cập các mô hình API ElevenLabs như Multilingual v2, Text-to-Dialogue v3 và Audio Isolation APIs thông qua nền tảng duy nhất. Bạn có thể thử nghiệm miễn phí và tích hợp dễ dàng.
Mô hình API giọng nói ElevenLabs để tạo và chỉnh sửa lời nói bằng AI
API TTS của ElevenLabs giúp tạo giọng nói AI với chất lượng cao
API TTS của ElevenLabs cung cấp các quy trình chuyển văn bản thành giọng nói linh hoạt thông qua các mô hình phụ chuyên biệt. API Multilingual V2 chuyển đổi văn bản thô thành lời nói tự nhiên, đảm bảo độ chính xác tuyệt đối về giọng nói. API Turbo V2.5 với độ trễ thấp giúp xác định mã ngôn ngữ rõ ràng, đảm bảo khả năng truy cập toàn cầu.
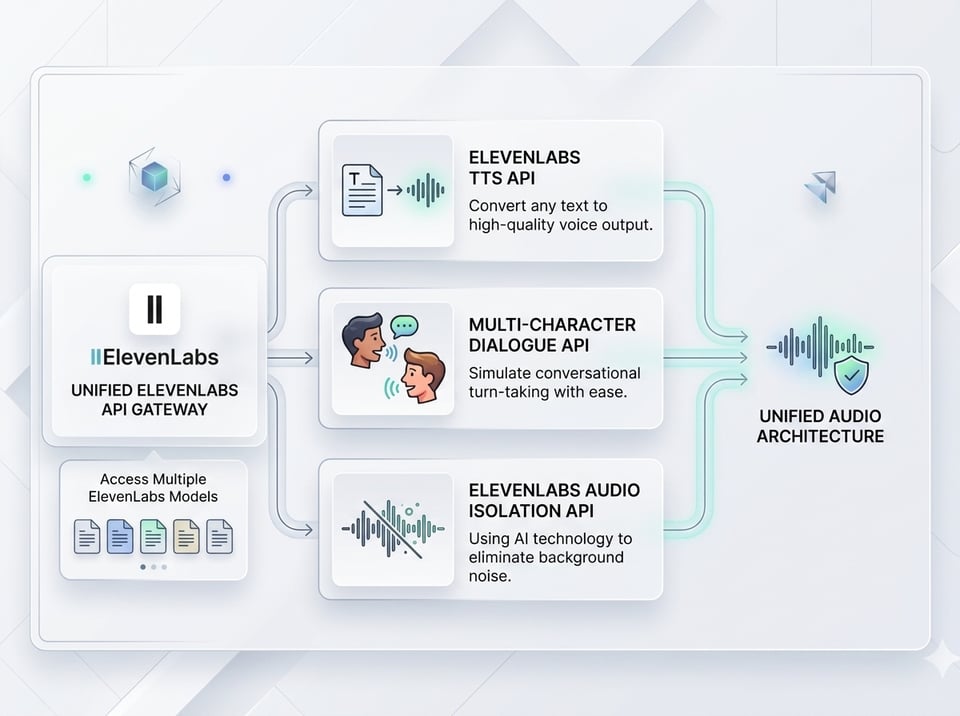
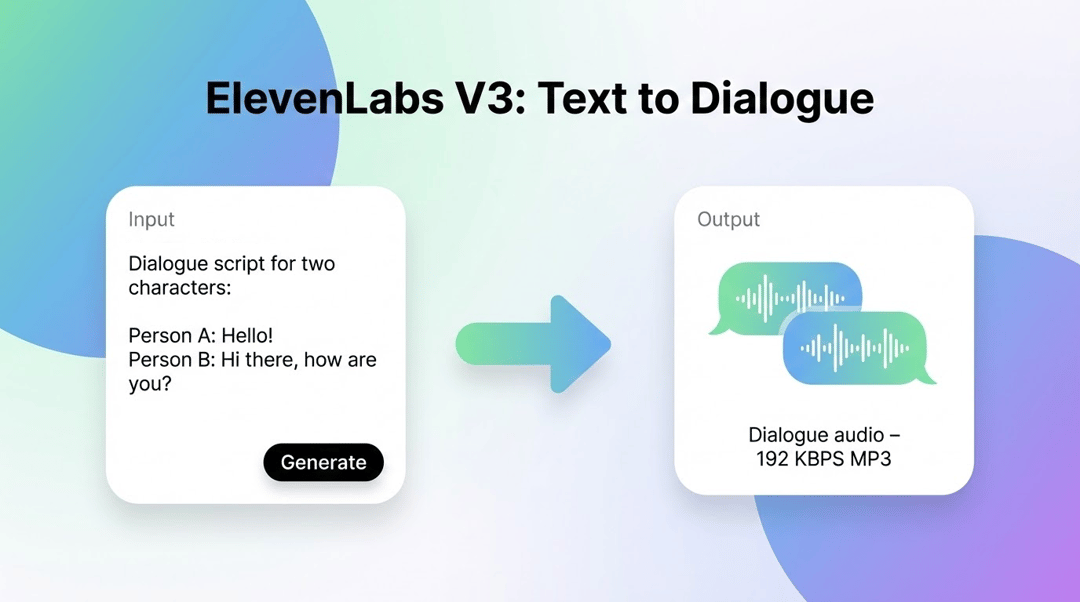
API giọng nói ElevenLabs Voice V3 hỗ trợ các luồng công việc hội thoại đa nhân vật
API ElevenLabs Voice V3 giúp tự động hóa quá trình chuyển đổi văn bản thành lời một cách dễ dàng và hiệu quả thông qua khả năng tổng hợp hội thoại đa nhân vật trên hơn 70 ngôn ngữ. Động cơ này hỗ trợ đọc trực tiếp các thẻ âm thanh nội tuyến, cho phép lập trình viên điều khiển cách phát lời bằng các biểu hiện phi ngôn ngữ như thì thầm, cười, thở dài hoặc nhấn mạnh điểm cụ thể.

API tách âm thanh ElevenLabs giúp tách âm thanh một cách tự động
API tách giọng nói ElevenLabs sử dụng công nghệ phân tách tần số thần kinh tiên tiến để trích xuất lời nói trong sạch từ các bản ghi có nhiễu hoặc bị lỗi. Được thiết kế dành cho phỏng vấn, podcast và phát trực tiếp, pipeline tách âm thanh chuyên dụng này giúp loại bỏ tiếng ồn một cách hiệu quả từ micro, tiếng xe cộ, tiếng ồn nền và nhạc trùng lặp.
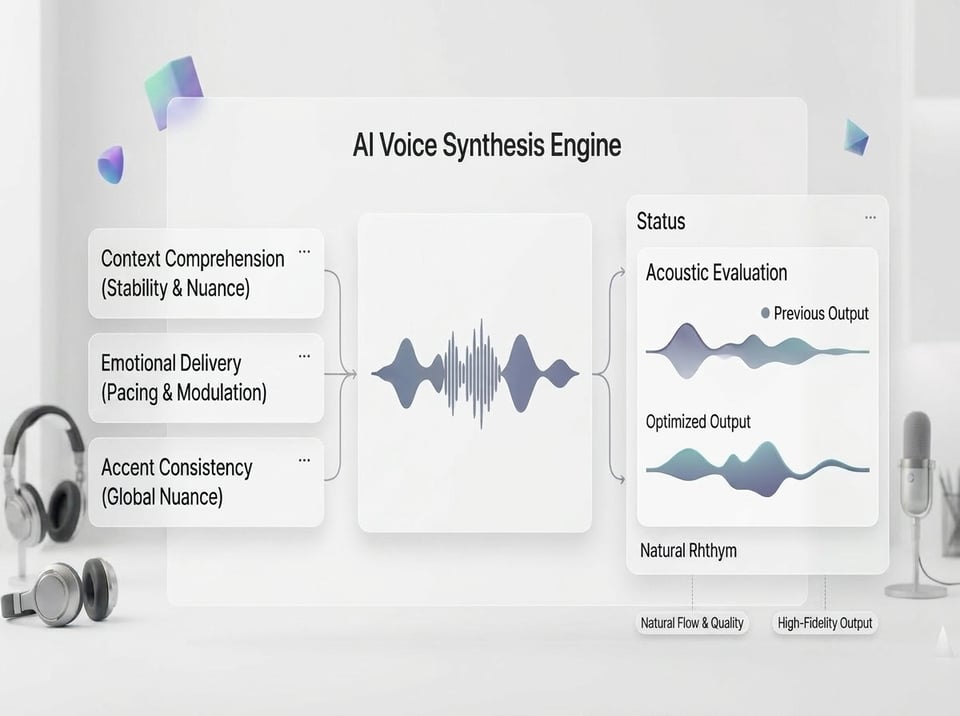
Media Format Compatibility & ElevenLabs AI API Payloads
Process standard UTF-8 text strings, structured JSON narrative arrays, and external media files in .mp3, .wav, .mp4, or .mov formats within a single, streamlined Asynchronous Audio Task API pipeline. Build scalable audio deal with tools and SaaS applications capable of parsing complex audio layouts generation loops inside one robust AI ecosystem.
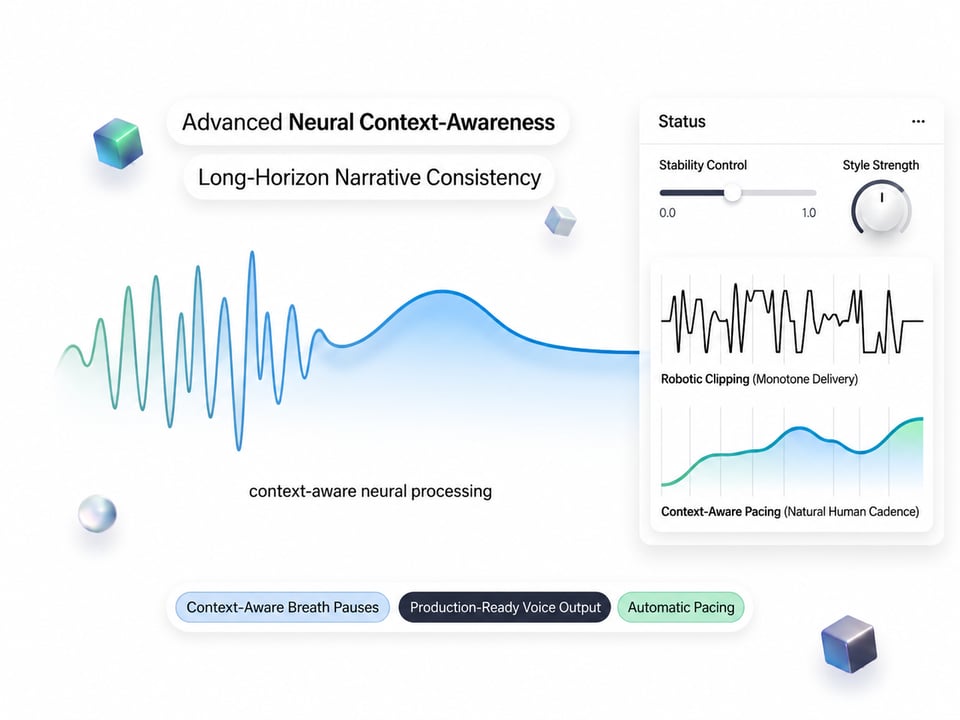
Tại sao nên chọn Kie.ai để truy cập ElevenLabs AI API?
Kiểm tra sau khi đăng ký bằng credit dùng thử miễn phí
Nền tảng cung cấp credit dùng thử miễn phí khi tạo tài khoản, cùng với môi trường sandbox tương tác. Giúp lập trình viên thử nghiệm các thông số mô hình, đo độ trễ endpoint thực tế và kiểm tra cấu trúc request/response trước khi triển khai sản phẩm.
Giá cước API tính theo từng lần sử dụng
Dịch vụ hoạt động theo hệ thống thanh toán theo từng lần sử dụng, phù hợp với nhu cầu sử dụng thông thường của nhà phát triển. Cấu trúc này theo dõi chính xác lượng tài nguyên tiêu thụ trong quá trình chuyển văn bản thành giọng nói, thực thi kịch bản hội thoại và xử lý giọng nói riêng lẻ, giúp các nhóm có thể mở rộng chi phí máy tính theo lượng ứng dụng đang hoạt động.
Hỗ trợ kỹ thuật 24/7 và hỗ trợ cơ sở hạ tầng
Hỗ trợ kỹ thuật và nhà phát triển luôn sẵn sàng 24/7. Nhóm kỹ thuật sẽ xử lý các vấn đề liên quan đến tích hợp API, tối ưu hóa dữ liệu, thời gian kết nối hết hạn và điều chỉnh tuyến đường xử lý đồng thời để đảm bảo ứng dụng luôn hoạt động ổn định.
Hướng dẫn cách sử dụng ElevenLabs API trên Kie.ai
Bước 1: Chọn endpoint ElevenLabs API phù hợp với nhu cầu của bạn
Chọn endpoint phù hợp với quy trình làm việc của bạn. Triển khai ElevenLabs TTS API để tạo giọng đọc đơn, chuyển sang ElevenLabs Voice V3 API để xử lý kịch bản đối thoại đa nhân vật, hoặc sử dụng Voice Isolation API để xử lý giảm tiếng ồn nền và làm sạch giọng nói sau sản xuất.
Bước 2: Thử nghiệm mô hình trong môi trường phát triển
Sử dụng môi trường phát triển của Kie.ai để kiểm tra các mô hình giọng nói đã chọn trước khi triển khai tích hợp. Nhập chuỗi văn bản tùy chỉnh, đánh giá các thuộc tính phát âm thời gian thực, và xác minh đầu vào bằng các credit dùng thử miễn phí trước khi viết script triển khai sản xuất.
Bước 3: Lấy khóa API và xem tài liệu hướng dẫn chi tiết
Tạo khóa truy cập API an toàn trong bảng điều khiển và xem tài liệu kỹ thuật thống nhất của nền tảng. Khám phá các trường cấu hình cần thiết—bao gồm định dạng yêu cầu, bảng giá credit, và các tham số điều chỉnh như độ ổn định và độ tương đồng—để giảm thiểu lỗi cấu hình trong quá trình triển khai.
Bước 4: Tích hợp pipeline vào quy trình làm việc
Kết nối cổng kết nối linh hoạt vào môi trường sản xuất, kiến trúc ứng dụng hoặc quy trình tạo nội dung tự động. Xây dựng các trình tạo giọng nói AI, trình đọc kịch bản, quy trình tổng hợp podcast tự động và dịch vụ vi mô cách âm âm thanh nâng cao thông qua một điểm tích hợp duy nhất.
Những gì các nhà phát triển có thể xây dựng bằng API ElevenLabs
Nền tảng tạo audiobook tự động
Phần mềm địa phương hóa video và phiên âm toàn cầu
Đạo diễn & Nhà biên tập – Làm sạch âm thanh thoại với ElevenLabs Audio Isolation API
Nền tảng podcast với đầy đủ nhân vật
What Developers Can Build With ElevenLabs API
Automated Audiobook Publishing Platforms
Developers can build long-form content deployment pipelines that ingest complete book manuscripts and output production-ready audio assets. Utilizing the ElevenLabs TTS API, these platforms convert massive text files into single-voice narrations with human-like breathing cadences, employing previous request IDs for continuous multi-chunk patching to maintain acoustic momentum across chapter boundaries.
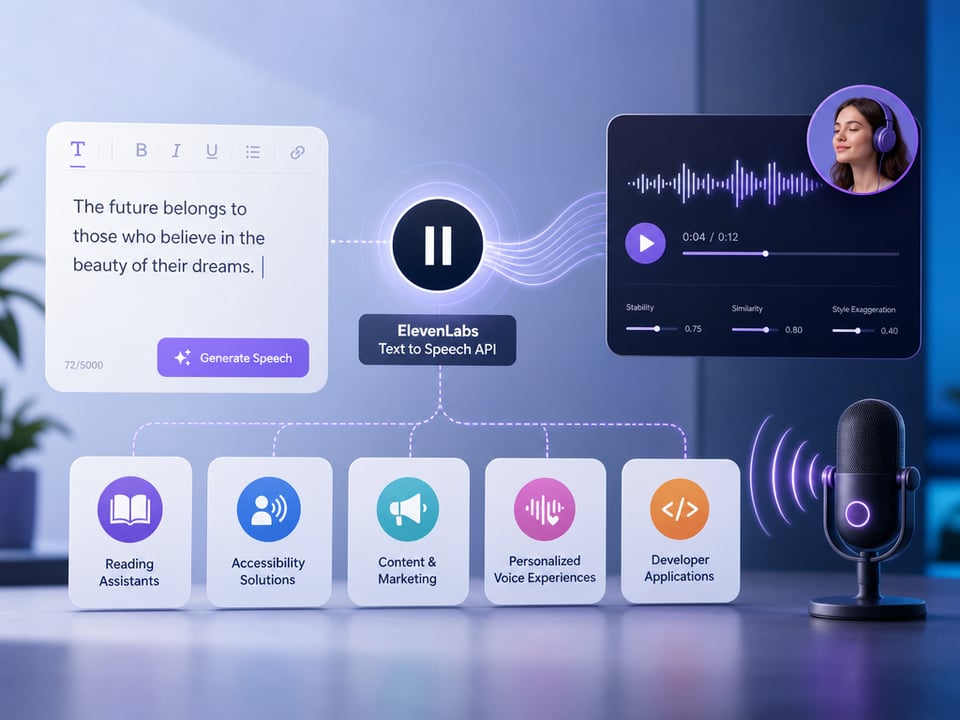
Global Video Localization and Dubbing Software
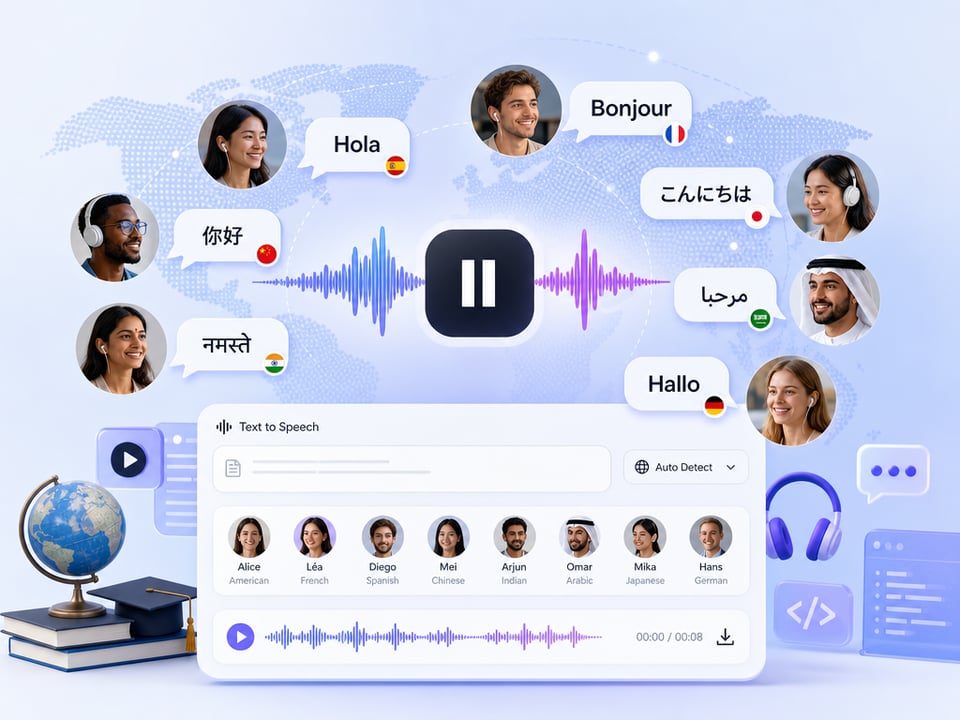
This application framework enables multi-market video adaptation by automating the voice-dubbing process for international distribution. By integrating the ElevenLabs TTS API (Multilingual V2), the system scales global video localization tools that translate text while preserving original speaker characteristics, regional accent nuances, and emotional profiles across different languages.
Filmmakers & Editors – Dialogue Polishing with ElevenLabs Audio Isolation API
Post-production teams and video editors can deploy automated audio cleaning pipelines to salvage compromised production audio directly from film sets or field recordings. Operating through the Voice Isolation API, this system allows filmmakers to upload dialogue clips from multi-format video containers up to 500MB, programmatically isolating raw human speech frequencies while filtering out severe wind noise, camera hums, and unpredictable environmental background chatter.

Virtual Full-Cast Podcast Platforms
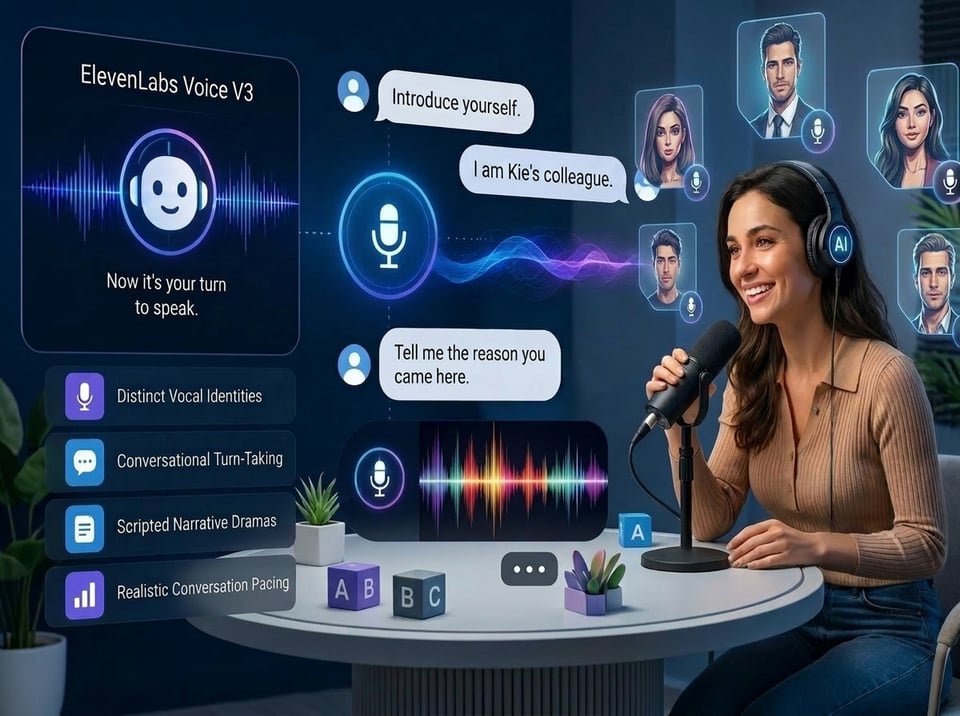
This use case involves building automated podcast production networks that simulate multi-host roundtables, corporate panel discussions, or scripted narrative dramas. Powered by the ElevenLabs Voice V3 API, the system orchestrates multi-speaker dialogue setups that handle conversational turn-taking, distinct vocal identities, and realistic conversation pacing.
Frequently Asked Questions About ElevenLabs API
How does Kie.ai’s unified billing model assist enterprises with cost control?
Instead of purchasing separate credit pools from multiple providers for text-to-speech and audio isolation, Kie.ai utilizes a single, pay-as-you-go credit architecture. Enterprises manage one centralized account to allocate resources freely across all ElevenLabs endpoints, simplifying ROI tracking and precise computing cost calculations.
What technical safeguards does Kie.ai provide during high-concurrency requests or API error events?
Kie.ai provides 24/7 continuous engineering support to maintain production uptime. Technical teams are available around the clock to assist with high-concurrency rate limiting adjustments, network connection timeouts, and request payload configuration troubleshooting.
Can the ElevenLabs API handle multi-character conversational generation?
Yes. The ElevenLabs Voice V3 API parses structured script arrays within a single payload. It automatically generates multi-speaker dialogue with distinct voice IDs, natural turn-taking, and inline emotional tags without requiring manual audio file stitching.
Does the ElevenLabs API support background noise mitigation and vocal separation?
Yes. The Voice Isolation API uses a neural frequency separation engine to process multi-format audio and video files. It strips out microphone hiss, room reverb, traffic rumbles, and background music, leaving a purified human conversational track.
Is there a sandbox environment to test ElevenLabs models prior to deployment?
Yes. Kie.ai provides complimentary credits and an interactive browser-based playground upon registration. Developers can use this environment to test parameters, evaluate vocal outputs, and validate payload structures before writing production code.
Can the Voice Isolation API extract vocal layers from mixed musical tracks?
Yes. The Voice Isolation API processes complex audio files to isolate human vocals from backing music, sound effects, and instrumental tracks. While optimized for dialogue clarity and background noise mitigation, its frequency separation engine effectively decouples the vocal layer from mixed audio beds, outputting a purified voice track suitable for further editing or remixing.