Seedance 2.5 on KIE is ByteDance’s upgraded AI video model, built for longer, more controllable video generation. It supports up to 30-second videos, multimodal references, precise editing, and improved consistency for more cinematic and production-ready creative workflows.
Wan3.0 is Alibaba’s next-generation all-in-one video generation model built for multimodal creation. It supports text, image, video, audio, and structured references to produce more consistent, realistic, and controllable video content with enhanced storytelling and editing capabilities.
Seedance 2.0 on KIE is a multimodal Al video model by ByteDance, optimized for fast and realistic video generation. It supports high-quality virtual human video creation with strong multi-shot consistency, enabling more lifelike and cinematic outputs across scenes.
GPT Image 2 is OpenAI’s next-gen image model built for stronger photorealism, cleaner image editing, sharper text rendering, and more polished product photography. Designed for more advanced visual workflows, it pushes image generation beyond basic text-to-image output and into higher-quality creative, commercial, and design-ready use cases.
Meet Nano Banana 2, Google’s Gemini 3.1 Flash Image model, now available via Kie AI API. Built for developers, it combines lightning-fast speed with Pro-level quality, accurate text rendering, strong character consistency, and scalable image generation and editing workflows.
Grok 4.6 is xAI’s latest frontier AI model, designed to enhance long-running agents, advanced reasoning, coding intelligence, and interactive AI experiences. Building on Grok 4.5, it delivers improved performance for complex multi-step tasks, knowledge work, software engineering, and creative applications.
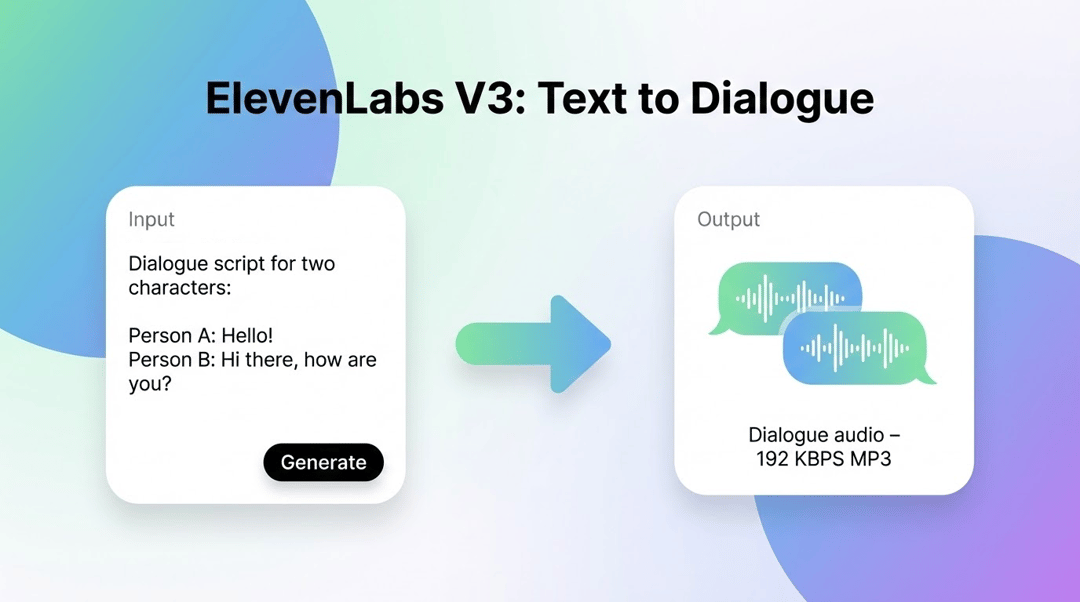

한 곳에서 ElevenLabs API 다국어 v2, 텍스트-다이얼로그 v3 및 기타 API 사용하기
다국어 v2, 텍스트-다이얼로그 v3, 오디오 분리 API 등 ElevenLabs API 모델을 하나의 플랫폼에서 무료 테스트와 유연한 통합으로 접근할 수 있습니다.
ElevenLabs 음성 API 모델 – AI 음성 생성 및 편집을 위한 플랫폼
고음질 음성 생성을 위한 ElevenLabs TTS API
ElevenLabs TTS API는 전문적인 하위 모델을 통해 다양한 텍스트-음성 변환 워크플로우를 제공합니다. Multilingual V2 API는 원문 텍스트를 완벽한 발음과 함께 자연스러운 음성으로 변환하고, Turbo V2.5 API는 다국어 지원을 위해 언어 코드를 지정하여 전 세계 사용자에게 접근성을 보장합니다.
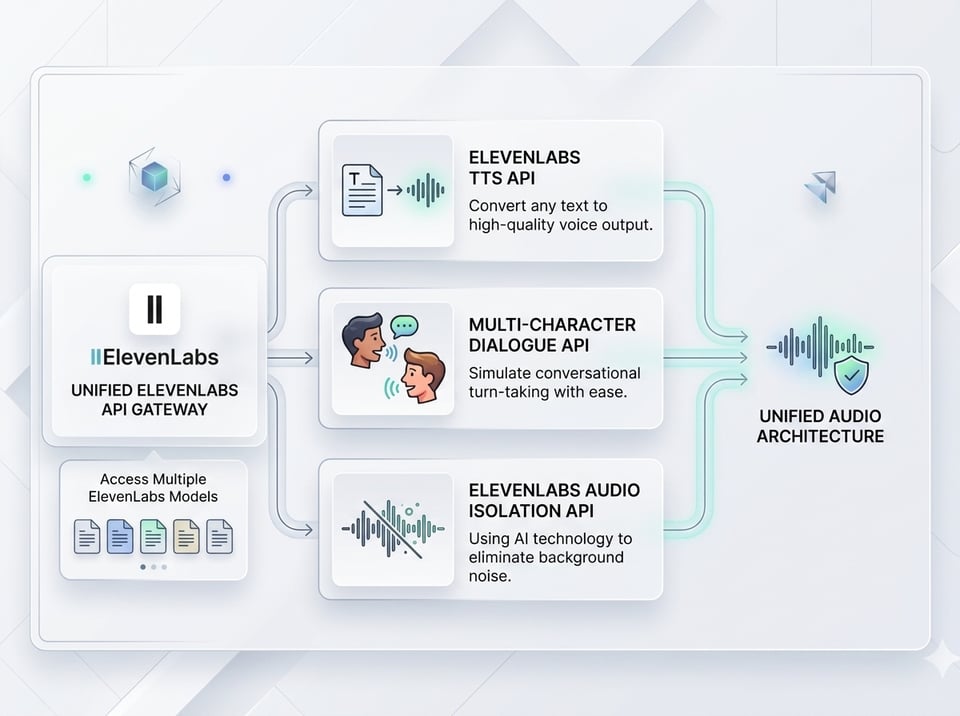
다중 캐릭터 대화형 워크플로우를 위한 ElevenLabs Voice V3 API
ElevenLabs Voice V3 API는 70개 이상 언어를 지원하는 다중 화자 대화 합성 기능을 통해 스크립트를 음성으로 자동 변환합니다. 이 엔진은 인라인 오디오 태그를 직접 해석할 수 있어, 개발자가 속삭임, 웃음, 한숨, 강조 구문 등 비언어적 표현을 프로그래밍 방식으로 음성 출력에 반영할 수 있습니다.

ElevenLabs 오디오 분리 API – 프로그래밍 방식의 오디오 분리 기능
ElevenLabs 음성 분리 API는 고급 신경망 주파수 분리 기술을 활용해 노이즈나 손상된 녹음에서 깨끗한 인간 음성을 추출합니다. 인터뷰, 팟캐스트, 라이브 스트리밍에 특화된 이 전용 분리 파이프라인은 마이크의 히스 소음, 교통 소음, 배경 음성, 중첩된 음악 트랙 등을 필터링하여 고품질의 음성만을 남깁니다.
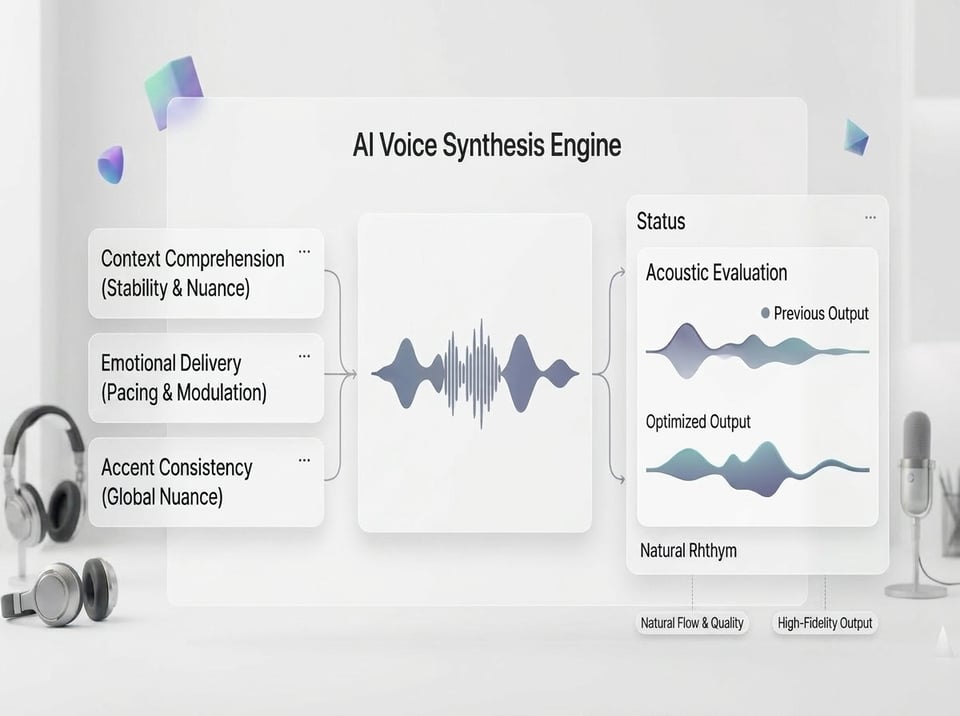
Media Format Compatibility & ElevenLabs AI API Payloads
Process standard UTF-8 text strings, structured JSON narrative arrays, and external media files in .mp3, .wav, .mp4, or .mov formats within a single, streamlined Asynchronous Audio Task API pipeline. Build scalable audio deal with tools and SaaS applications capable of parsing complex audio layouts generation loops inside one robust AI ecosystem.
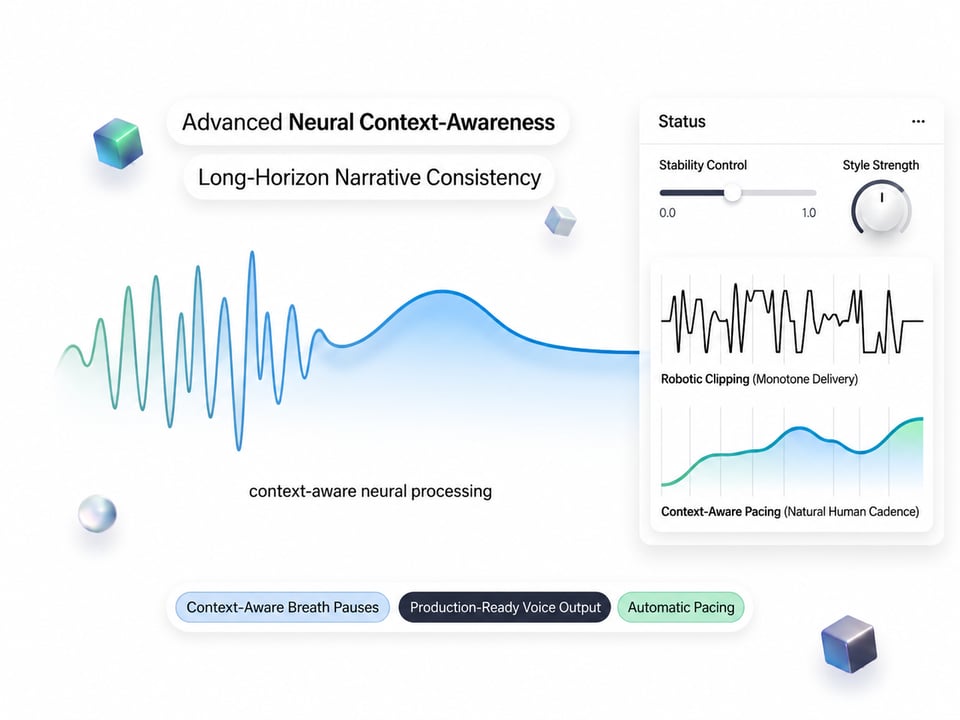
Kie.ai가 ElevenLabs AI API를 선택하는 이유
가입 후 무료 체험 크레딧으로 테스트
계정 생성 시 무료 테스트 크레딧을 제공하며, 상호작용 가능한 샌드박스 환경을 통해 개발자는 모델 파라미터를 실험하고, 실제 지연 시간을 측정하며, 요청 및 응답 구조를 검증할 수 있습니다. 이는 실제 서비스 배포 전에 필수적인 단계입니다.
사용 요금제
서비스는 표준 개발자 사용 패턴에 맞춘 사용량 기반 결제 시스템으로 운영됩니다. 이 구조는 텍스트-음성 변환 렌더링, 대화형 스크립트 실행, 음성 분리 파이프라인 등 각 리소스 소비량을 정확히 추적하여, 팀이 애플리케이션의 활성화된 볼륨에 따라 컴퓨팅 비용을 유연하게 조절할 수 있도록 합니다.
항상 사용 가능한 기술 지원 및 인프라 지원이 제공됩니다.
기술 모니터링 및 개발자 지원은 언제든지 이용 가능합니다. 엔지니어링 지원 팀은 API 통합, 페이로드 최적화, 연결 타임아웃, 고병렬 라우팅 조정 등 기술적 문의에 대해 대응하여 애플리케이션의 가동률을 유지하는 데 도움을 줍니다.
Kie.ai에서 ElevenLabs API 사용 방법
단계 1: 필요한 ElevenLabs API 엔드포인트 선택
목표 워크플로우에 맞는 적합한 엔드포인트를 선택하세요. ElevenLabs TTS API를 사용해 단일 음성의 서술을 구현하고, 구조화된 다중 화자 대화 스크립트에는 ElevenLabs Voice V3 API로 전환하거나, 프로그래밍 방식의 배경 소음 감소 및 보컬 포스트 프로덕션 정리 작업을 위해 Voice Isolation API를 활용하세요.
단계 2: 온라인 테스트 환경에서 모델 테스트하기
Kie.ai 개발자 테스트 환경에서 선택한 음성 모델을 통합 전에 테스트해 보세요. 사용자 정의 텍스트를 입력하고 실시간 음성 속성을 평가한 후, 프로덕션 배포 스크립트를 작성하기 전 무료 체험 크레딧으로 대상 데이터 구조를 검증할 수 있습니다.
단계 3: API 키 생성 및 문서 확인하기
대시보드에서 안전한 API 접근 키를 생성하고 플랫폼 통합 기술 문서를 확인하세요. 요청 페이로드 형식, 크레딧 요금제, 그리고 안정성(stability)과 similarity_boost와 같은 조정 옵션 등 핵심 설정 필드를 검토하여 배포 시 발생할 수 있는 설정 문제를 최소화하세요.
단계 4: 워크플로우에 연결하기
유연한 게이트웨이를 프로덕션 환경, 애플리케이션 아키텍처 또는 자동화된 콘텐츠 생성 워크플로우에 연결하세요. 단일 동시 처리가 가능한 통합 인터페이스를 통해 확장 가능한 AI 음성 생성기, 반응형 스크립트 리더, 자동 팟캐스트 합성 파이프라인 및 고급 음향 분리 마이크로서비스를 구축할 수 있습니다.
ElevenLabs API로 개발자들이 만들 수 있는 것
오디오북 자동 제작 플랫폼
글로벌 비디오 다국어 처리 및 더빙 소프트웨어
영화 제작자 및 편집자 – ElevenLabs 음성 분리 API로 대사 편집하기
가상 전체 배우가 참여하는 팟캐스트 플랫폼
What Developers Can Build With ElevenLabs API
Automated Audiobook Publishing Platforms
Developers can build long-form content deployment pipelines that ingest complete book manuscripts and output production-ready audio assets. Utilizing the ElevenLabs TTS API, these platforms convert massive text files into single-voice narrations with human-like breathing cadences, employing previous request IDs for continuous multi-chunk patching to maintain acoustic momentum across chapter boundaries.
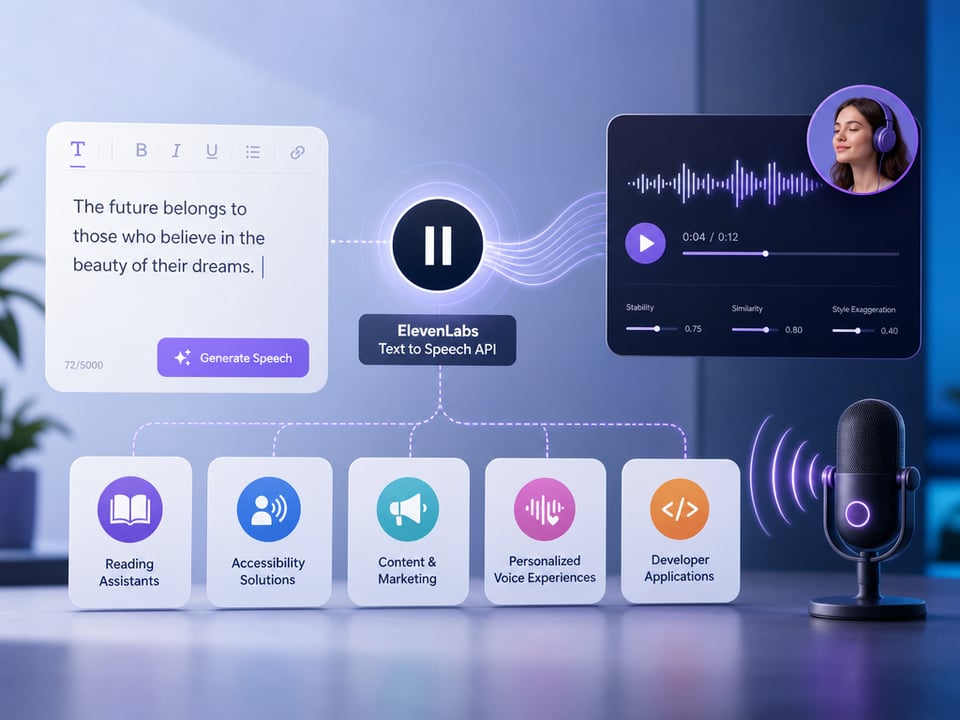
Global Video Localization and Dubbing Software
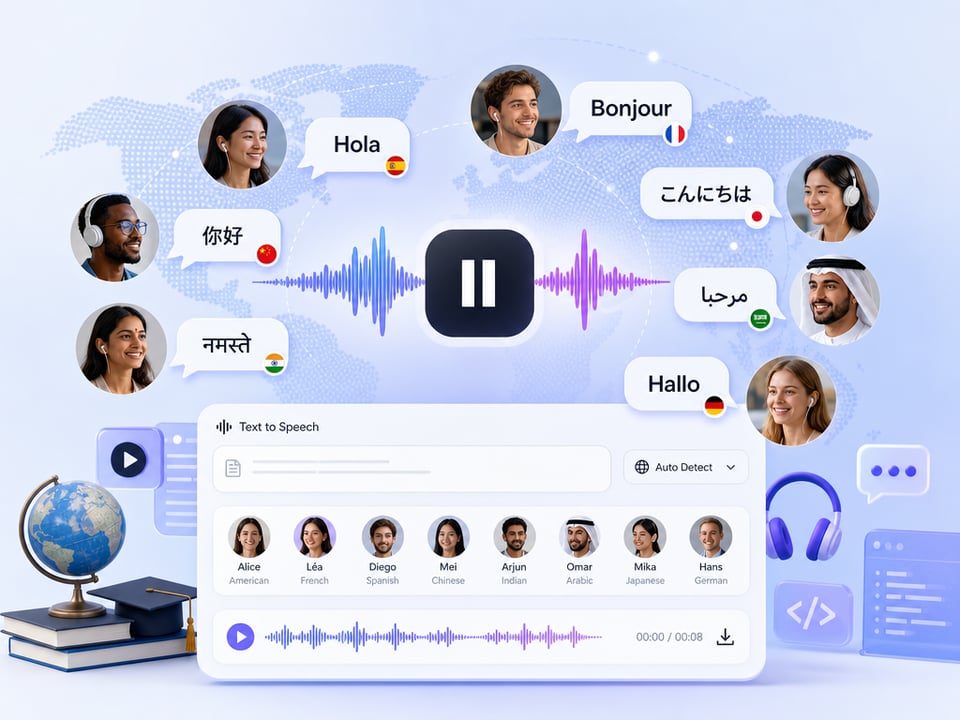
This application framework enables multi-market video adaptation by automating the voice-dubbing process for international distribution. By integrating the ElevenLabs TTS API (Multilingual V2), the system scales global video localization tools that translate text while preserving original speaker characteristics, regional accent nuances, and emotional profiles across different languages.
Filmmakers & Editors – Dialogue Polishing with ElevenLabs Audio Isolation API
Post-production teams and video editors can deploy automated audio cleaning pipelines to salvage compromised production audio directly from film sets or field recordings. Operating through the Voice Isolation API, this system allows filmmakers to upload dialogue clips from multi-format video containers up to 500MB, programmatically isolating raw human speech frequencies while filtering out severe wind noise, camera hums, and unpredictable environmental background chatter.

Virtual Full-Cast Podcast Platforms
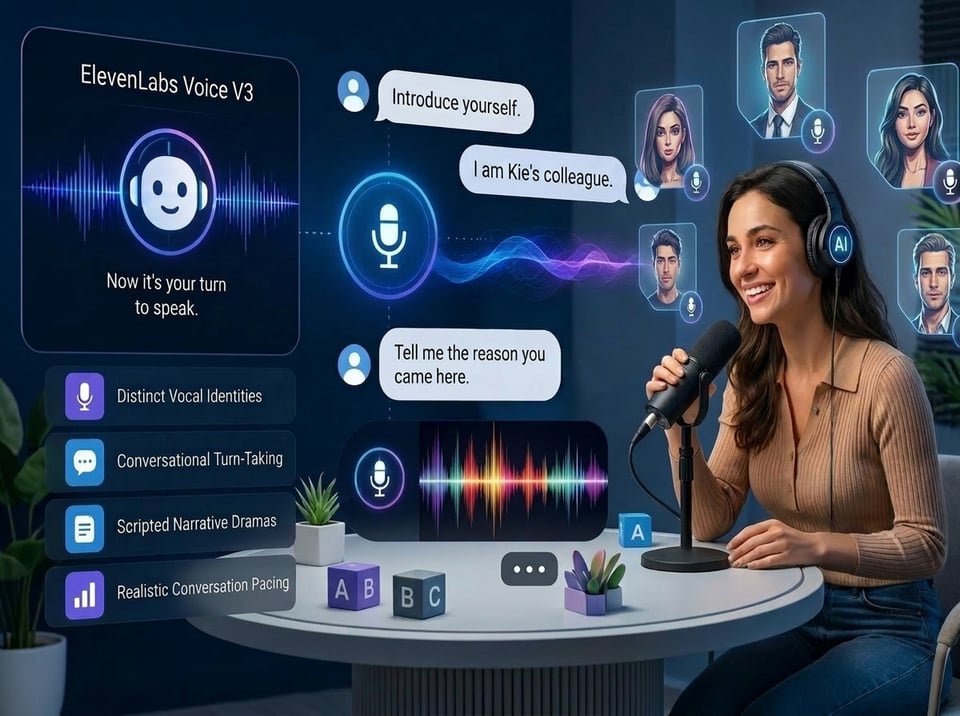
This use case involves building automated podcast production networks that simulate multi-host roundtables, corporate panel discussions, or scripted narrative dramas. Powered by the ElevenLabs Voice V3 API, the system orchestrates multi-speaker dialogue setups that handle conversational turn-taking, distinct vocal identities, and realistic conversation pacing.
Frequently Asked Questions About ElevenLabs API
How does Kie.ai’s unified billing model assist enterprises with cost control?
Instead of purchasing separate credit pools from multiple providers for text-to-speech and audio isolation, Kie.ai utilizes a single, pay-as-you-go credit architecture. Enterprises manage one centralized account to allocate resources freely across all ElevenLabs endpoints, simplifying ROI tracking and precise computing cost calculations.
What technical safeguards does Kie.ai provide during high-concurrency requests or API error events?
Kie.ai provides 24/7 continuous engineering support to maintain production uptime. Technical teams are available around the clock to assist with high-concurrency rate limiting adjustments, network connection timeouts, and request payload configuration troubleshooting.
Can the ElevenLabs API handle multi-character conversational generation?
Yes. The ElevenLabs Voice V3 API parses structured script arrays within a single payload. It automatically generates multi-speaker dialogue with distinct voice IDs, natural turn-taking, and inline emotional tags without requiring manual audio file stitching.
Does the ElevenLabs API support background noise mitigation and vocal separation?
Yes. The Voice Isolation API uses a neural frequency separation engine to process multi-format audio and video files. It strips out microphone hiss, room reverb, traffic rumbles, and background music, leaving a purified human conversational track.
Is there a sandbox environment to test ElevenLabs models prior to deployment?
Yes. Kie.ai provides complimentary credits and an interactive browser-based playground upon registration. Developers can use this environment to test parameters, evaluate vocal outputs, and validate payload structures before writing production code.
Can the Voice Isolation API extract vocal layers from mixed musical tracks?
Yes. The Voice Isolation API processes complex audio files to isolate human vocals from backing music, sound effects, and instrumental tracks. While optimized for dialogue clarity and background noise mitigation, its frequency separation engine effectively decouples the vocal layer from mixed audio beds, outputting a purified voice track suitable for further editing or remixing.